Thursday, December 21, 2023

Java String Template

The first time you look at a Java String Template, it feels right and wrong simultaneously. 

String first = "John";
String last = "Smith";
String info = STR. "My first name is \{ first } and my last name is \{ last }" ;       

Right because the result of the final statement is with the placeholders correctly evaluated and filled in. It feels wrong because of the strange new "STR." expression and the way the placeholders are escaped "\{ }" 

However now that I have looked at it for some time, the reasoning does make sense and I have gotten used to the new syntax.

So let’s start with the motivation first, I will mostly follow the structure of the well-explained JEP that goes with this feature.


Motivation

It has traditionally been cumbersome to compose a string using data and expressions, taking an example from the JEP, say to compose:

10 plus 20 equals 30

would look something like this:
int x = 10;
int y = 20;
String s = new StringBuilder()
        .append(x)
        .append(" plus ")
        .append(y)
        .append(" equals ")
        .append(x + y)
        .toString();
With String Template such extensive composing is no longer needed and looks something like this:

int x = 10;
int y = 20;
String s = STR. "\{ x } plus \{ y } equals \{ x + y }" ;


Workings

So there are a few parts to it:
  1. the String template \{ x } plus \{ y } equals \{ x + y }, which is intuitive, the placeholder variables and expressions in a String template are escaped using \{ } syntax
  2. brand new expression syntax, STR.<string template>
  3. STR is the “Template Processor”, that returns the final processed string
It is illegal to have a String template without a String Template Processor, if I were to try without having it, the following is the error I get in Intellij:


String Template Processor

String Template Processor is the part that provides special powers, imagine processors that can avoid SQL injection while crafting a SQL statement!

Looking closely first at a raw String Template, itis obtained by using a RAW String Template Processor

String first = "John";
String last = "Smith";
StringTemplate st = RAW. "My first name is \{ first } and my last name is \{ last }" ;


And is composed of two sets of data:

  • fragments, which is [“My first name is” , “and my last name is” , “”] in the template above, the pieces of fixed text around the template placeholders
  • values — which are the resolved placeholders, so in my example they are [“John”, “Smith”]

A Template Processor simply uses the “fragments” and “values” to put the final output together, for eg, I can implement a custom Template Processor that capitalizes the fragments the following way:

StringTemplate.Processor<String, RuntimeException> UPPER =
        StringTemplate.Processor.of((StringTemplate st) -> {
            StringBuilder sb = new StringBuilder();
            Iterator<String> fragIter = st.fragments().iterator();
            for (Object value : st.values()) {
            sb.append(fragIter.next().toUpperCase());
            sb.append(value);
            }
            sb.append(fragIter.next());
            return sb.toString();
        });
You can imagine highly specialized String Template Processors coming up that can handle the scenario of SQL injection attacks for example.

Conclusion

String Template is a welcome addition to the Java ecosystem and simplifies scenarios where a string needs to be composed of various expressions. It is still a preview feature as of Java 21, so its use in production code is not recommended until it is GA, but it is worth checking out to see how it works.

These are the resources that go with this article:

String Template JEP — https://openjdk.org/jeps/430

Saturday, April 29, 2023

EventArc with CloudRun

 Google Cloud EventArc provides a simple way to act on events generated by a variety of Google Cloud Services.


Consider an example.

When a Cloud Build trigger is run, I want to be notified of this event -


Eventarc makes this integration simple


The internals of how it does this is documented well. Based on the source, the event is either received by EventArc directly or via Cloud Audit Logs. EventArc then dispatches the event to the destination via another pub/sub topic that it maintains. 

These underlying details are well hidden though, so as a developer concerned only about consuming the Build Events, I can focus on the payload of the event and ignore the mechanics of how EventArc gets the message from the source to my service.

Sample EventArc listener

Since I am interested in just the events and its payload, all I have to do from an application perspective is to expose an HTTP endpoint responding to a POST message with the content being the event that I am concerned about. Here is such an endpoint in Java using Spring Boot as the framework:

@RestController
public class EventArcMessageController {
    ...
    
    @RequestMapping(value = "/", method = RequestMethod.POST)
    public Mono<ResponseEntity<JsonNode>> receiveMessage(
            @RequestBody JsonNode body, @RequestHeader Map<String, String> headers) {
        LOGGER.info("Received message: {}, headers: {}", JsonUtils.writeValueAsString(body, objectMapper), headers);
        return Mono.just(ResponseEntity.ok(body));
    }
}


The full sample is available here

In this specific instance all the endpoint is doing is to log the message and the headers accompanying the message. As long as the response code is 200, EventArc would consider the handling to be successful. 

EventArc supports over 130 Google Cloud Services, so consuming myriad events from a bunch of services is easy.

EventArc Trigger

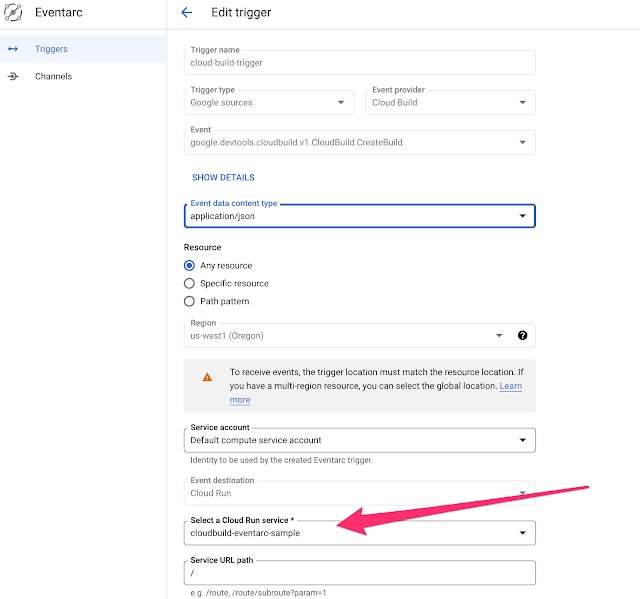
Once I have the EventArc deployed as a Cloud Run service, to integrate this with the Cloud Build Events in EventArc, all I have to do is to create an EventArc trigger. This can be done using the UI:


or using command line:

gcloud eventarc triggers update cloud-build-trigger \
--location=us-west1 \
--destination-run-service=cloudbuild-eventarc-sample \
--destination-run-region=us-west1 \
--destination-run-path="/" \
--event-filters="type=google.cloud.audit.log.v1.written" \
--event-filters="serviceName=cloudbuild.googleapis.com" \
--event-filters="methodName=google.devtools.cloudbuild.v1.CloudBuild.CreateBuild"

and that is it, EventArc handles all the underlying details of the integration.


Conclusion

I have the full java code available here which shows what a full code would look like. EventArc makes it very simple to integrate events from Google Cloud Services with custom applications.


Thursday, December 29, 2022

Bigtable Pagination in Java

 Consider a set of rows stored in Bigtable table called “people”:


My objective is to be able to paginate a few records at a time, say with each page containing 4 records:


Page 1:


Page 2:


Page 3:


High-Level Approach

A high level approach to doing this is to introduce two parameters:

  • Offset — the point from which to retrieve the records.
  • Limit — the number of records to retrieve per page
Limit in all cases is 4 in my example. Offset provides some way to indicate where to retrieve the next set of records from. Bigtable orders the record lexicographically using the key of each row, so one way to indicate offset is by using the key of the last record on a page. Given this, and using a marker offset of empty string for the first page, offset and record for each page looks like this:

Page 1 — offset: “”, limit: 4


Page 2 — offset: “person#id-004”, limit: 4

Page 3 — offset: “person#id-008”, limit: 4


The challenge now is in figuring out how to retrieve a set of records given a prefix, an offset, and a limit.

Retrieving records given a prefix, offset, limit

Bigtable java client provides a “readRows” api, that takes in a Query and returns a list of rows.

import com.google.cloud.bigtable.data.v2.BigtableDataClient
import com.google.cloud.bigtable.data.v2.models.Query
import com.google.cloud.bigtable.data.v2.models.Row

val rows: List<Row> = bigtableDataClient.readRows(query).toList()

Now, Query has a variant that takes in a prefix and returns rows matching the prefix:

import com.google.cloud.bigtable.data.v2.BigtableDataClient
import com.google.cloud.bigtable.data.v2.models.Query
import com.google.cloud.bigtable.data.v2.models.Row

val query: Query = Query.create("people").limit(limit).prefix(keyPrefix)
val rows: List<Row> = bigtableDataClient.readRows(query).toList()        

This works for the first page, however, for subsequent pages, the offset needs to be accounted for.

A way to get this to work is to use a Query that takes in a range:

import com.google.cloud.bigtable.data.v2.BigtableDataClient
import com.google.cloud.bigtable.data.v2.models.Query
import com.google.cloud.bigtable.data.v2.models.Row
import com.google.cloud.bigtable.data.v2.models.Range

val range: Range.ByteStringRange = 
    Range.ByteStringRange
        .unbounded()
        .startOpen(offset)
        .endOpen(end)

val query: Query = Query.create("people")
                    .limit(limit)
                    .range(range)

The problem with this is to figure out what the end of the range should be. This is where a neat utility that the Bigtable Java library provides comes in. This utility given a prefix of “abc”, calculates the end of the range to be “abd”

import com.google.cloud.bigtable.data.v2.models.Range

val range = Range.ByteStringRange.prefix("abc")
Putting this all together, a query that fetches paginated rows at an offset looks like this:

val query: Query =
    Query.create("people")
        .limit(limit)
        .range(Range.ByteStringRange
            .prefix(keyPrefix)
            .startOpen(offset))

val rows: List<Row> = bigtableDataClient.readRows(query).toList()

When returning the result, the final key needs to be returned so that it can be used as the offset for the next page, this can be done in Kotlin by having the following type:

data class Page<T>(val data: List<T>, val nextOffset: String)

Conclusion

I have a full example available here — this pulls in the right library dependencies and has all the mechanics of pagination wrapped into a working sample.

Cloud Run Health Checks — Spring Boot App

 Cloud Run services now can configure startup and liveness probes for a running container.


The startup probe is for determining when a container has cleanly started up and is ready to take traffic. A Liveness probe kicks off once a container has started up, to ensure that the container remains functional — Cloud Run would restart a container if the liveness probe fails.


Implementing Health Check Probes

A Cloud Run service can be described using a manifest file and a sample manifest looks like this:


apiVersion: serving.knative.dev/v1
kind: Service
metadata:
  annotations:
    run.googleapis.com/ingress: all
  name: health-cloudrun-sample
spec:
  template:
    metadata:
      annotations:
        autoscaling.knative.dev/maxScale: '5'
        autoscaling.knative.dev/minScale: '1'
    spec:
      containers:
        image: us-west1-docker.pkg.dev/sample-proj/sample-repo/health-app-image:latest

        startupProbe:
          httpGet:
            httpHeaders:
            - name: HOST
              value: localhost:8080
            path: /actuator/health/readiness
          initialDelaySeconds: 15
          timeoutSeconds: 1
          failureThreshold: 5
          periodSeconds: 10

        livenessProbe:
          httpGet:
            httpHeaders:
            - name: HOST
              value: localhost:8080
            path: /actuator/health/liveness
          timeoutSeconds: 1
          periodSeconds: 10
          failureThreshold: 5

        ports:
        - containerPort: 8080
          name: http1
        resources:
          limits:
            cpu: 1000m
            memory: 512Mi


This manifest can then be used for deployment to Cloud Run the following way:

gcloud run services replace sample-manifest.yaml --region=us-west1

Now, coming back to the manifest, the startup probe is defined this way:

startupProbe:
  httpGet:
    httpHeaders:
    - name: HOST
      value: localhost:8080
    path: /actuator/health/readiness
  initialDelaySeconds: 15
  timeoutSeconds: 1
  failureThreshold: 5
  periodSeconds: 10

It is set to make an http request to a /actuator/health/readiness path. There is an explicit HOST header also provided, this is temporary though as Cloud Run health checks currently have a bug where this header is missing from the health check requests.

The rest of the properties indicate the following:

  • initialDelaySeconds — delay for performing the first probe
  • timeoutSeconds — timeout for the health check request
  • failureThreshold — number of tries before the container is marked as not ready
  • periodSeconds — the delay between probes

Once the startup probe succeeds, Cloud Run would mark the container as being available to handle the traffic.

A livenessProbe follows a similar pattern:

livenessProbe:
  httpGet:
    httpHeaders:
    - name: HOST
      value: localhost:8080
    path: /actuator/health/liveness
  timeoutSeconds: 1
  periodSeconds: 10
  failureThreshold: 5

From a Spring Boot application perspective, all that needs to be done is to enable the Health check endpoints as described here


Conclusion

Start-Up probe ensures that a container receives traffic only when ready and a Liveness probe ensures that the container remains healthy during its operation, else gets restarted by the infrastructure. These health probes are a welcome addition to the already excellent feature set of Cloud Run.


Wednesday, December 28, 2022

Skaffold for Cloud Run and Local Environments

In one of my previous posts, I had explored using Cloud Deploy to deploy to a Cloud Run environment. Cloud Deploy uses a Skaffold file to internally orchestrate the steps required to build an image, adding the coordinates of the image to the manifest files and deploying it to a runtime. This works out great, not so much for local development and testing though. The reason is a lack of local Cloud Run runtime.

A good alternative is to simply use a local distribution of Kubernetes — say a minikube or kind. This will allow Skaffold to be used to its full power — with an ability to provide a quick development loop, debug, etc. I have documented some of the features here. The catch however is that there will now need to be two different sets of details of the environments maintained along with their corresponding sets of manifests — ones targeting Cloud Run, targeting minikube.


Skaffold patching is a way to do this and this post will go into the high-level details of the approach.

Skaffold Profiles and Patches

My original Skaffold configuration looks like this, targeting a Cloud Run environment:

apiVersion: skaffold/v3alpha1
kind: Config
metadata:
  name: clouddeploy-cloudrun-skaffold
manifests:
  kustomize:
    paths:
      - manifests/base
build:
  artifacts:
    - image: clouddeploy-cloudrun-app-image
      jib: { }
profiles:
  - name: dev
    manifests:
      kustomize:
        paths:
          - manifests/overlays/dev
  - name: prod
    manifests:
      kustomize:
        paths:
          - manifests/overlays/prod
deploy:
  cloudrun:
    region: us-west1-a

The “deploy.cloudrun” part indicates that it is targeting a Cloud Run environment.

So now, I want a different behavior in “local” environment, the way to do this in skaffold is to create a Skaffold profile that specifies what is different about this environment:

apiVersion: skaffold/v3alpha1
kind: Config
metadata:
  name: clouddeploy-cloudrun-skaffold
manifests:
  kustomize:
    paths:
      - manifests/base
build:
  artifacts:
    - image: clouddeploy-cloudrun-app-image
      jib: { }
profiles:
  - name: local
    # Something different on local
  - name: dev
    manifests:
      kustomize:
        paths:
          - manifests/overlays/dev
  - name: prod
    manifests:
      kustomize:
        paths:
          - manifests/overlays/prod
deploy:
  cloudrun:
    region: us-west1-a

I have two things different on local,

the deploy environment will be a minikube-based Kubernetes environment
the manifests file will be for this Kubernetes environment.
For the first requirement:

apiVersion: skaffold/v3alpha1
kind: Config
metadata:
  name: clouddeploy-cloudrun-skaffold
manifests:
  kustomize:
    paths:
      - manifests/base
build:
  artifacts:
    - image: clouddeploy-cloudrun-app-image
      jib: { }
profiles:
  - name: local
    patches:
      - op: remove
        path: /deploy/cloudrun
    deploy:
      kubectl: { }
  - name: dev
    manifests:
      kustomize:
        paths:
          - manifests/overlays/dev
  - name: prod
    manifests:
      kustomize:
        paths:
          - manifests/overlays/prod
deploy:
  cloudrun:
    region: us-west1-a

To specify the deploy environment where patches come, here the patch indicates that I want to remove Cloudrun as a deployment environment and add in Kubernetes.

And for the second requirement of generating a Kubernetes manifest, a rawYaml tag is introduced:

apiVersion: skaffold/v3alpha1
kind: Config
metadata:
  name: clouddeploy-cloudrun-skaffold
manifests:
  kustomize:
    paths:
      - manifests/base
build:
  artifacts:
    - image: clouddeploy-cloudrun-app-image
      jib: { }
profiles:
  - name: local
    manifests:
      kustomize: { }
      rawYaml:
        - kube/app.yaml
    patches:
      - op: remove
        path: /deploy/cloudrun
    deploy:
      kubectl: { }
  - name: dev
    manifests:
      kustomize:
        paths:
          - manifests/overlays/dev
  - name: prod
    manifests:
      kustomize:
        paths:
          - manifests/overlays/prod
deploy:
  cloudrun:
    region: us-west1-a

In this way a combination of Skaffold profiles and patches are used for tweaking the local deployment for Minikube.

Activating Profiles

When testing on local the “local” profile can be activated this way with Skaffold — with a -p flag:

skaffold dev -p local

One of the most useful command that I got to use is the “diagnose” command in skaffold which clearly showed what skaffold configuration is active for specific profiles:

skaffold diagnose -p local

which generated this resolved configuration for me:

apiVersion: skaffold/v3
kind: Config
metadata:
  name: clouddeploy-cloudrun-skaffold
build:
  artifacts:
  - image: clouddeploy-cloudrun-app-image
    context: .
    jib: {}
  tagPolicy:
    gitCommit: {}
  local:
    concurrency: 1
manifests:
  rawYaml:
  - /Users/biju/learn/clouddeploy-cloudrun-sample/kube/app.yaml
  kustomize: {}
deploy:
  kubectl: {}
  logs:
    prefix: container

Conclusion

There will likely be better support for Cloud Run on a local environment, for now, a minikube based Kubernetes is a good stand-in. Skaffold with profiles and patches can target this environment on a local box. This allows Skaffold features like quick development loop, debugging, etc to be activated while an application is in the process of being developed.

Wednesday, November 16, 2022

CloudEvent Basics

CloudEvent is a way of describing events in a common way. This specification is starting to be adopted across different event producers across Cloud Providers, which over time will provide these benefits:

  • Consistency: The format of an event looks the same irrespective of the source producing the event, systems which transmit the event and systems consuming the event. 
  • Tooling: Since there is a consistency in format, tooling and libraries can depend on this common format

Cloud Event Sample

One of the ways I have got my head around CloudEvent is to look at samples. Here is a sample Cloud Event published by a Google Cloud Pub/Sub topic, this is in a json format(there are other formats to represent a CloudEvent, for eg, avro or protobuf):
{
  "data": {
    "subscription": "projects/test-project/subscriptions/my-subscription",
    "message": {
      "attributes": {
        "attr1": "attr1-value"
      },
      "data": "dGVzdCBtZXNzYWdlIDM=",
      "messageId": "message-id",
      "publishTime": "2021-02-05T04:06:14.109Z",
      "orderingKey": "ordering-key"
    }
  },
  "datacontenttype": "application/json",
  "id": "3103425958877813",
  "source": "//pubsub.googleapis.com/projects/test-project/topics/my-topic",
  "specversion": "1.0",
  "time": "2021-02-05T04:06:14.109Z",
  "type": "google.cloud.pubsub.topic.v1.messagePublished"
}
Some of the elements in this event are:

  1. “id” which uniquely identifies the event
  2. “source” which identifies the system generating the event
  3. “specversion” identifies the CloudEvent specificiation that this event complies with
  4. “type” defining the type of event produced by the source system
  5. “datacontenttype” which describes the content type of the data
  6. “data”, which is the actual event payload, the structure of this specifically can change based on the “type” of event.
The “id”, “source”, “specversion” and “type” fields are mandatory

Cloud Event Extensions

In certain cases there will be additional attributes that may be needed to be understood across systems which produce and consume messages. A good example is distributed tracing where tracing attributes may need to be present in event data, to support these cases, events can have extension attributes. An example is the following:

{
  "data": {
    "subscription": "projects/test-project/subscriptions/my-subscription",
    "message": {
      "attributes": {
        "attr1": "attr1-value"
      },
      "data": "dGVzdCBtZXNzYWdlIDM=",
      "messageId": "message-id",
      "publishTime": "2021-02-05T04:06:14.109Z",
      "orderingKey": "ordering-key"
    }
  },
  "datacontenttype": "application/json",
  "id": "3103425958877813",
  "source": "//pubsub.googleapis.com/projects/test-project/topics/my-topic",
  "specversion": "1.0",
  "time": "2021-02-05T04:06:14.109Z",
  "type": "google.cloud.pubsub.topic.v1.messagePublished",
  "traceparent": "00-4bf92f3577b34da6a3ce929d0e0e4736-00f067aa0ba902b7-01",
  "tracestate": "rojo=00-4bf92f3577b34da6a3ce929d0e0e4736-00f067aa0ba902b7-01,congo=lZWRzIHRoNhcm5hbCBwbGVhc3VyZS4"
}

where “traceparent” and “tracestate” capture the distribution tracing related attributes. Some of the other extension types are documented here.

Data Attribute

The event payload is contained in the “data” attribute (or can be base 64 encoded into a “data_base64” attribute). The structure of the data attribute is entirely depends on the event type. There is a level of specification that can be specified by the event type using an additional attribute called “dataschema”.

Consider another sample for a log entry data related event in Google Cloud:

{
  "data": {
    "insertId": "1234567",
    "logName": "projects/test-project/logs/cloudaudit.googleapis.com%2Fdata_access",
    "protoPayload": {
      "authenticationInfo": {
        "principalEmail": "robot@test-project.iam.gserviceaccount.com"
      },
      "methodName": "jobservice.jobcompleted",
      "requestMetadata": {
        "callerIp": "2620:15c:0:200:1a75:e914:115b:e970",
        "callerSuppliedUserAgent": "google-cloud-sdk357.0.0 (gzip),gzip(gfe)",
        "destinationAttributes": {
          
        },
        "requestAttributes": {
          
        }
      },
      "resourceName": "projects/test-project/jobs/sample-job",
      "serviceData": {
        "jobCompletedEvent": {
          "eventName": "query_job_completed",
          "job": {
            "jobConfiguration": {
              "query": {
                "createDisposition": "CREATE_IF_NEEDED",
                "defaultDataset": {
                  
                },
                "destinationTable": {
                  "datasetId": "sample-dataset",
                  "projectId": "test-project",
                  "tableId": "sample-table"
                },
                "query": "sample-query",
                "queryPriority": "QUERY_INTERACTIVE",
                "statementType": "SELECT",
                "writeDisposition": "WRITE_TRUNCATE"
              }
            }
          }
        }
      },
      "serviceName": "bigquery.googleapis.com",
      "status": {
        
      }
    },
    "receiveTimestamp": "2021-11-25T21:56:00.653866570Z",
    "resource": {
      "labels": {
        "project_id": "test-project"
      },
      "type": "bigquery_resource"
    },
    "severity": "INFO",
    "timestamp": "2021-11-25T21:56:00.276607Z"
  },
  "datacontenttype": "application/json; charset=utf-8",
  "dataschema": "https://googleapis.github.io/google-cloudevents/jsonschema/google/events/cloud/audit/v1/LogEntryData.json",
  "id": "projects/test-project/logs/cloudaudit.googleapis.com%2Fdata_access1234567123456789",
  "methodName": "jobservice.jobcompleted",
  "recordedTime": "2021-11-25T21:56:00.276607Z",
  "resourceName": "projects/test-project/jobs/sample-job",
  "serviceName": "bigquery.googleapis.com",
  "source": "//cloudaudit.googleapis.com/projects/test-project/logs/data_access",
  "specversion": "1.0",
  "subject": "bigquery.googleapis.com/projects/test-project/jobs/sample-job",
  "time": "2021-11-25T21:56:00.653866570Z",
  "type": "google.cloud.audit.log.v1.written"
}

The “data” field is fairly complicated here, however see how there is a reference to a “dataschema” pointing to this document — https://googleapis.github.io/google-cloudevents/jsonschema/google/events/cloud/audit/v1/LogEntryData.json

which describes the elements in the “data”, using json schema specification

Conclusion

CloudEvents attempts to solve the issue of different event sources using different ways to represent an event, by providing a common specification.

This blog post provides a quick overview of the specification, in a future post I will go over how this is useful for writing eventing systems on Google Cloud.

Saturday, September 24, 2022

Cloud Deploy with Cloud Run

Google Cloud Deploy is a service to continuously deploy to Google Cloud Application runtimes. It has supported Google Kubernetes Engine(GKE) so far, and now is starting to support Cloud Run. This post is about a quick trial of this new and exciting support in Cloud Deploy. 

It may be simpler to explore the entire sample which is available in my github repo here - https://github.com/bijukunjummen/clouddeploy-cloudrun-sample 


End to end Flow

The sample attempts to do the following:


A Cloud Build based build first builds an image. This image is handed over to Cloud Deploy which deploys to Cloud Run. A "dev" and "prod" target is simulated by the Cloud Run applications having names prefixed with the environment name.

Building an image

There are way too many ways to build a container image, my personal favorite is  the excellent Google jib tool which requires a simple plugin to be in place to create AND publish a container image. Once an image is created, the next task is to get the tagged image name for use with say a Kubernetes deployment manifest. 


Skaffold does a great job of orchestrating these two steps, creating an image and rendering the application runtime manifests with the image locations. Since the deployment is to a Cloud Run environment, the manifest looks something like this:


Now, manifest for each target environment may look a little different, so for eg in my case the application name targeted towards dev environment has a "dev-" prefix and for prod environment has a "prod-" prefix. This is where another tool called Kustomize fits in. Kustomize is fairly intuitive, it expresses the variations for each environment as a patch file, so for eg, in my case where I want to prefix the name of the application in the dev environment with a "dev-", the Kustomize configuration looks something like this:

So now, we have 3 tools:
  1. For building an image - Google Jib
  2. Generating the manifests based on environment - Kustomize
  3. Rending the image name in the manifests - Skaffold
Skaffold does a great job of wiring all the tools together, and looks something like this for my example:


Deploying the Image

In the Google Cloud Environment, Cloud Build is used for calling Skaffold and building the image, I have a cloudbuild.yaml file available with my sample, which shows how skaffold is invoked and the image built.

Let's come to the topic of the post, about deploying this image to Cloud Run using Cloud Deploy. Cloud Deploy uses a configuration file to describe where the image needs to be deployed, which is Cloud Run in this instance and how the deployment needs to be promoted across environments. The environments are referred to as "targets" and look like this in my configuration:

They point to the project and region for the Cloud Run service.

Next is the configuration to describe how the pipeline will take the application through the targets:

This simply shows that application will be first deployed to the "dev" target and then promoted to the "prod" target after approval.

The "profiles" in the each of the stages show the profile that will be activated in skaffold, which simply determines which overlay of kustomize will be used to create the manifest.

That covers the entire Cloud Deploy configuration. The next step once the configuration file is ready is to create the deployment pipeline, which is done using a command which looks like this:

gcloud deploy apply --file=clouddeploy.yaml --region=us-west1

and registers the pipeline with Cloud Deploy service.


So just to quickly recap, I now have the image built by Cloud Build, the manifests generated using skaffold, kustomize, and a pipeline registered with Cloud Deploy, the next step is to trigger the pipeline for the image and the artifacts, which is done through another command, which is hooked up to Cloud Build:
gcloud deploy releases create release-$SHORT_SHA --delivery-pipeline clouddeploy-cloudrun-sample --region us-west1 --build-artifacts artifacts.json

This would trigger the deploy to the different Cloud Run targets - "dev" in my case to start with:


Once deployed, I have a shiny Cloud Run app all ready to accept requests!


This can now be promoted to my "prod" target with a manual approval process:


Conclusion

Cloud Deploy's support for Cloud Run works great, it takes a familiar tooling with Skaffold typically meant for Kubernetes manifests and uses it cleverly for Cloud Run deployment flows. I look forward to more capabilities in Cloud Deploy with support for Blue/Green, Canary deployment models.

Sunday, September 4, 2022

Skaffold for Local Java App Development

Skaffold is a tool which handles the workflow of building, pushing and deploying container images and has the added benefit of facilitating an excellent local dev loop. 

In this post I will be exploring using Skaffold for local development of a Java based application


Installing Skaffold

Installing Skaffold locally is straightforward, and explained well here. It works great with minikube as a local kubernetes development environment. 


Skaffold Configuration

My sample application is available in a github repository here - https://github.com/bijukunjummen/hello-skaffold-gke

Skaffold requires at a minimum, a configuration expressed in a skaffold.yml file, with details of 

  • How to build an image
  • Where to push the image 
  • How to deploy the image - Kubernetes artifacts which should be hydrated with the details of the published image and used for deployment.

In my project, the skaffold.yml file looks like this:

apiVersion: skaffold/v2beta16
kind: Config
metadata:
  name: hello-skaffold-gke
build:
  artifacts:
  - image: hello-skaffold-gke
    jib: {}
deploy:
  kubectl:
    manifests:
    - kubernetes/hello-deployment.yaml
    - kubernetes/hello-service.yaml

This tells Skaffold:

  • that the container image should be built using the excellent jib tool
  • The location of the kubernetes deployment artifacts, in my case a deployment and a service describing the application
The Kubernetes manifests need not hardcode the container image tag, instead  they can use a placeholder which gets hydrated by Skaffold:

apiVersion: apps/v1
kind: Deployment
metadata:
  name: hello-skaffold-gke-deployment
spec:
  replicas: 1
  selector:
    matchLabels:
      app: hello-skaffold-gke
  template:
    metadata:
      labels:
        app: hello-skaffold-gke
    spec:
      containers:
        - name: hello-skaffold-gke
          image: hello-skaffold-gke
          ports:
            - containerPort: 8080
The image section gets populated with real tagged image name by Skaffold. 

Now that we have a Skaffold descriptor in terms of skaffold.yml file and Kubernetes manifests, let's see some uses of Skaffold.

Building a local Image

A local image is built using the "skaffold build" command, trying it on my local environment:

skaffold build --file-output artifacts.json

results in an image published to the local docker registry, along with a artifact.json file with a content pointing to the created image

{
  "builds": [
    {
      "imageName": "hello-skaffold-gke",
      "tag": "hello-skaffold-gke:a44382e0cd08ba65be1847b5a5aad099071d8e6f351abd88abedee1fa9a52041"
    }
  ]
}

If I wanted to tag the image with the coordinates to the Artifact Registry, I can specify an additional flag "default-repo", the following way:

skaffold build --file-output artifacts.json --default-repo=us-west1-docker.pkg.dev/myproject/sample-repo

resulting in a artifacts.json file with content that looks like this:

{
  "builds": [
    {
      "imageName": "hello-skaffold-gke",
      "tag": "us-west1-docker.pkg.dev/myproject/sample-repo/hello-skaffold-gke:a44382e0c008bf65be1847b5a5aad099071d8e6f351abd88abedee1fa9a52041"
    }
  ]
}
The kubernetes manifests can now be hydrated using a command which looks like this:

skaffold render -a artifacts.json --digest-source=local

which hydrates the manifests, and the output looks like this:

apiVersion: apps/v1
kind: Deployment
metadata:
  name: hello-skaffold-gke-deployment
  namespace: default
spec:
  replicas: 1
  selector:
    matchLabels:
      app: hello-skaffold-gke
  template:
    metadata:
      labels:
        app: hello-skaffold-gke
    spec:
      containers:
      - image: us-west1-docker.pkg.dev/myproject/sample-repo/hello-skaffold-gke:a44382e0c008bf65be1847b5a5aad099071d8e6f351abd88abedee1fa9a52041
        name: hello-skaffold-gke
        ports:
        - containerPort: 8080
---
apiVersion: v1
kind: Service
metadata:
  name: hello-skaffold-gke-service
  namespace: default
spec:
  ports:
  - name: hello-skaffold-gke
    port: 8080
  selector:
    app: hello-skaffold-gke
  type: LoadBalancer
The right image name now gets plugged into the Kubernetes manifests and can be used for deploying to any Kubernetes environment.

Deploying

Local Development loop with Skaffold

The additional benefit of having a Skaffold configuration file is in the excellent local development loop provided by Skaffold. All that needs to be done to get into the development loop is to run the following command:

skaffold dev --port-forward

which builds an image, renders the kubernetes artifacts pointing to the image and deploying the Kubernetes artifacts to the relevant local Kubernetes environment, minikube in my case:

➜  hello-skaffold-gke git:(main) ✗ skaffold dev --port-forward
Listing files to watch...
 - hello-skaffold-gke
Generating tags...
 - hello-skaffold-gke -> hello-skaffold-gke:5aa5435-dirty
Checking cache...
 - hello-skaffold-gke: Found Locally
Tags used in deployment:
 - hello-skaffold-gke -> hello-skaffold-gke:a44382e0c008bf65be1847b5a5aad099071d8e6f351abd88abedee1fa9a52041
Starting deploy...
 - deployment.apps/hello-skaffold-gke-deployment created
 - service/hello-skaffold-gke-service created
Waiting for deployments to stabilize...
 - deployment/hello-skaffold-gke-deployment is ready.
Deployments stabilized in 2.175 seconds
Port forwarding service/hello-skaffold-gke-service in namespace default, remote port 8080 -> http://127.0.0.1:8080
Press Ctrl+C to exit
Watching for changes...
The dev loops kicks in if any of the file is changed in the project, the image gets rebuilt and deployed again and is surprisingly quick with a tool like jib for creating images.

Debugging with Skaffold

Debugging also works great with skaffold, it starts the appropriate debugging agent for the language being used, so for java, if I were to run the following command:

skaffold debug --port-forward

and attach a debugger in Intellij using a "Remote process" pointing to the debug port


It would pause execution when a code with breakpoint is invoked!


Debugging Kubernetes artifacts

Since real Kubernetes artifacts are being used in the dev loop, we get to test the artifacts and see if there is any typos in them. So for eg, if I were to make a mistake and refer to "port" as "por", it would show up in the dev loop with an error the following way:

WARN[0003] deployer cleanup:kubectl create: running [kubectl --context minikube create --dry-run=client -oyaml -f /Users/biju/learn/hello-skaffold-gke/kubernetes/hello-deployment.yaml -f /Users/biju/learn/hello-skaffold-gke/kubernetes/hello-service.yaml]
 - stdout: "apiVersion: apps/v1\nkind: Deployment\nmetadata:\n  name: hello-skaffold-gke-deployment\n  namespace: default\nspec:\n  replicas: 1\n  selector:\n    matchLabels:\n      app: hello-skaffold-gke\n  template:\n    metadata:\n      labels:\n        app: hello-skaffold-gke\n    spec:\n      containers:\n      - image: hello-skaffold-gke\n        name: hello-skaffold-gke\n        ports:\n        - containerPort: 8080\n"
 - stderr: "error: error validating \"/Users/biju/learn/hello-skaffold-gke/kubernetes/hello-service.yaml\": error validating data: [ValidationError(Service.spec.ports[0]): unknown field \"por\" in io.k8s.api.core.v1.ServicePort, ValidationError(Service.spec.ports[0]): missing required field \"port\" in io.k8s.api.core.v1.ServicePort]; if you choose to ignore these errors, turn validation off with --validate=false\n"
 - cause: exit status 1  subtask=-1 task=DevLoop
kubectl create: running [kubectl --context minikube create --dry-run=client -oyaml -f /Users/biju/learn/hello-skaffold-gke/kubernetes/hello-deployment.yaml -f /Users/biju/learn/hello-skaffold-gke/kubernetes/hello-service.yaml]
 - stdout: "apiVersion: apps/v1\nkind: Deployment\nmetadata:\n  name: hello-skaffold-gke-deployment\n  namespace: default\nspec:\n  replicas: 1\n  selector:\n    matchLabels:\n      app: hello-skaffold-gke\n  template:\n    metadata:\n      labels:\n        app: hello-skaffold-gke\n    spec:\n      containers:\n      - image: hello-skaffold-gke\n        name: hello-skaffold-gke\n        ports:\n        - containerPort: 8080\n"
 - stderr: "error: error validating \"/Users/biju/learn/hello-skaffold-gke/kubernetes/hello-service.yaml\": error validating data: [ValidationError(Service.spec.ports[0]): unknown field \"por\" in io.k8s.api.core.v1.ServicePort, ValidationError(Service.spec.ports[0]): missing required field \"port\" in io.k8s.api.core.v1.ServicePort]; if you choose to ignore these errors, turn validation off with --validate=false\n"
 - cause: exit status 1
This is a great way to make sure that the Kubernetes manifests are tested in some way before deployment

Conclusion

Skaffold is an awesome tool to have in my toolbox, it facilitates building of container images, tagging them with sane names, hydrating the Kubernetes manifests using the images, deploying the manifests to a Kubernetes environment. In addition it provides a great development and debugging loop.

Wednesday, July 6, 2022

Google Cloud Function Gradle Plugin

 It is easy to develop a Google Cloud Function using Java with Gradle as the build tool. It is however not so simple to test it locally.

The current recommended approach to testing especially with gradle is very complicated. It requires pulling in Invoker libraries and adding a custom task to run the invoker function.

I have now authored a gradle plugin which makes local testing way more easier!


Problem

The way the Invoker is added in for a Cloud Function Gradle project looks like this today:

This has a lot of opaque details, for eg, what does the configurations of invoker even mean, what is the magical task that is being registered?

Fix

Now contrast it with the approach with the plugin:


All the boiler plate is now gone, configuration around the function class, which port to start it up on much more simplified. Adding this new plugin contributes a task that can be invoked the following way:

./gradlew cloudFunctionRun
It would start up an endpoint using which the function can be tested locally.

Conclusion

It may be far easier to see fully working samples incorporating this plugin. These samples are available here —


Thursday, June 23, 2022

Google Cloud Functions (2nd Gen) Java Sample

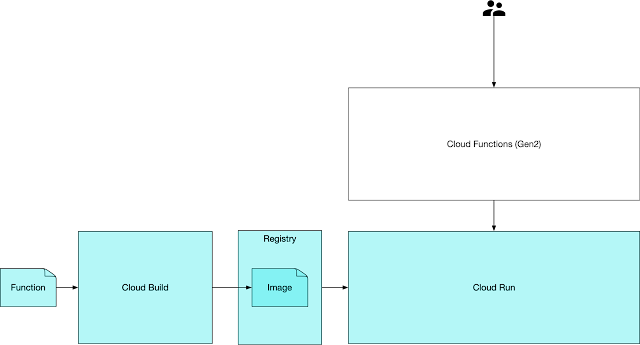
Cloud Functions (2nd Gen) is Google’s Serverless Functions as a Service Platform. 2nd Generation is now built on top of the excellent Google Cloud Run as a base. Think of Google Cloud Run as a Serverless environment for running containers which respond to events(http being the most basic, all sorts of other events via eventarc).


The blue area above shows the flow of code, the Google Cloud cli for Cloud Function, orchestrates the flow where the source code is placed in Google Cloud Storage bucket, a Cloud Build is triggered to build this code, package it into a container and finally this container is run using Cloud Run which the user can access via Cloud Functions console. Cloud Functions essentially becomes a pass through to Cloud Run.

The rest of this post will go into the details of how such a function can be written using Java.

tl;dr — sample code is available here — https://github.com/bijukunjummen/http-cloudfunction-java-gradle, and has all the relevant pieces hooked up.

Method Signature

To expose a function to respond to http events is fairly straightforward, it just needs to conform to the functions framework interface, for java it is available here — https://github.com/GoogleCloudPlatform/functions-framework-java

To pull in this dependency using gradle as the build tool looks like this:
  
  compileOnly("com.google.cloud.functions:functions-framework-api:1.0.4")

The dependency is required purely for compilation, at runtime the dependency is provided through a base image that Functions build time uses.

The function signature looks like this:

Testing the Function

This function can be tested locally using an Invoker that is provided by the functions-framework-api, my code https://github.com/bijukunjummen/http-cloudfunction-java-gradle shows how it can be hooked up with gradle, suffice to say that invoker allows an endpoint to brought up and tested with utilities like curl.

Deploying the Function

Now comes the easy part about deploying the function. Since a lot of Google Cloud Services need to be orchestrated to get a function deployed — GCS, Cloud Build, Cloud Run and Cloud Function, the command line to deploy the function does a great job of indicating which services need to be activated, the command to run looks like this:

gcloud beta functions deploy java-http-function \
--gen2 \
--runtime java17 \
--trigger-http \
--entry-point functions.HelloHttp \
--source ./build/libs/ \
--allow-unauthenticated    
    

Note that atleast for Java, it is sufficient to build the code locally and provide the built uber jar(jar with all dependencies packaged in) as the source.

Once deployed, the endpoint can be found using the following command:

gcloud beta functions describe java-http-function --gen2
and the resulting endpoint accessed via a curl command!

curl https://java-http-function-abc-uw.a.run.app
Hello World

What is Deployed

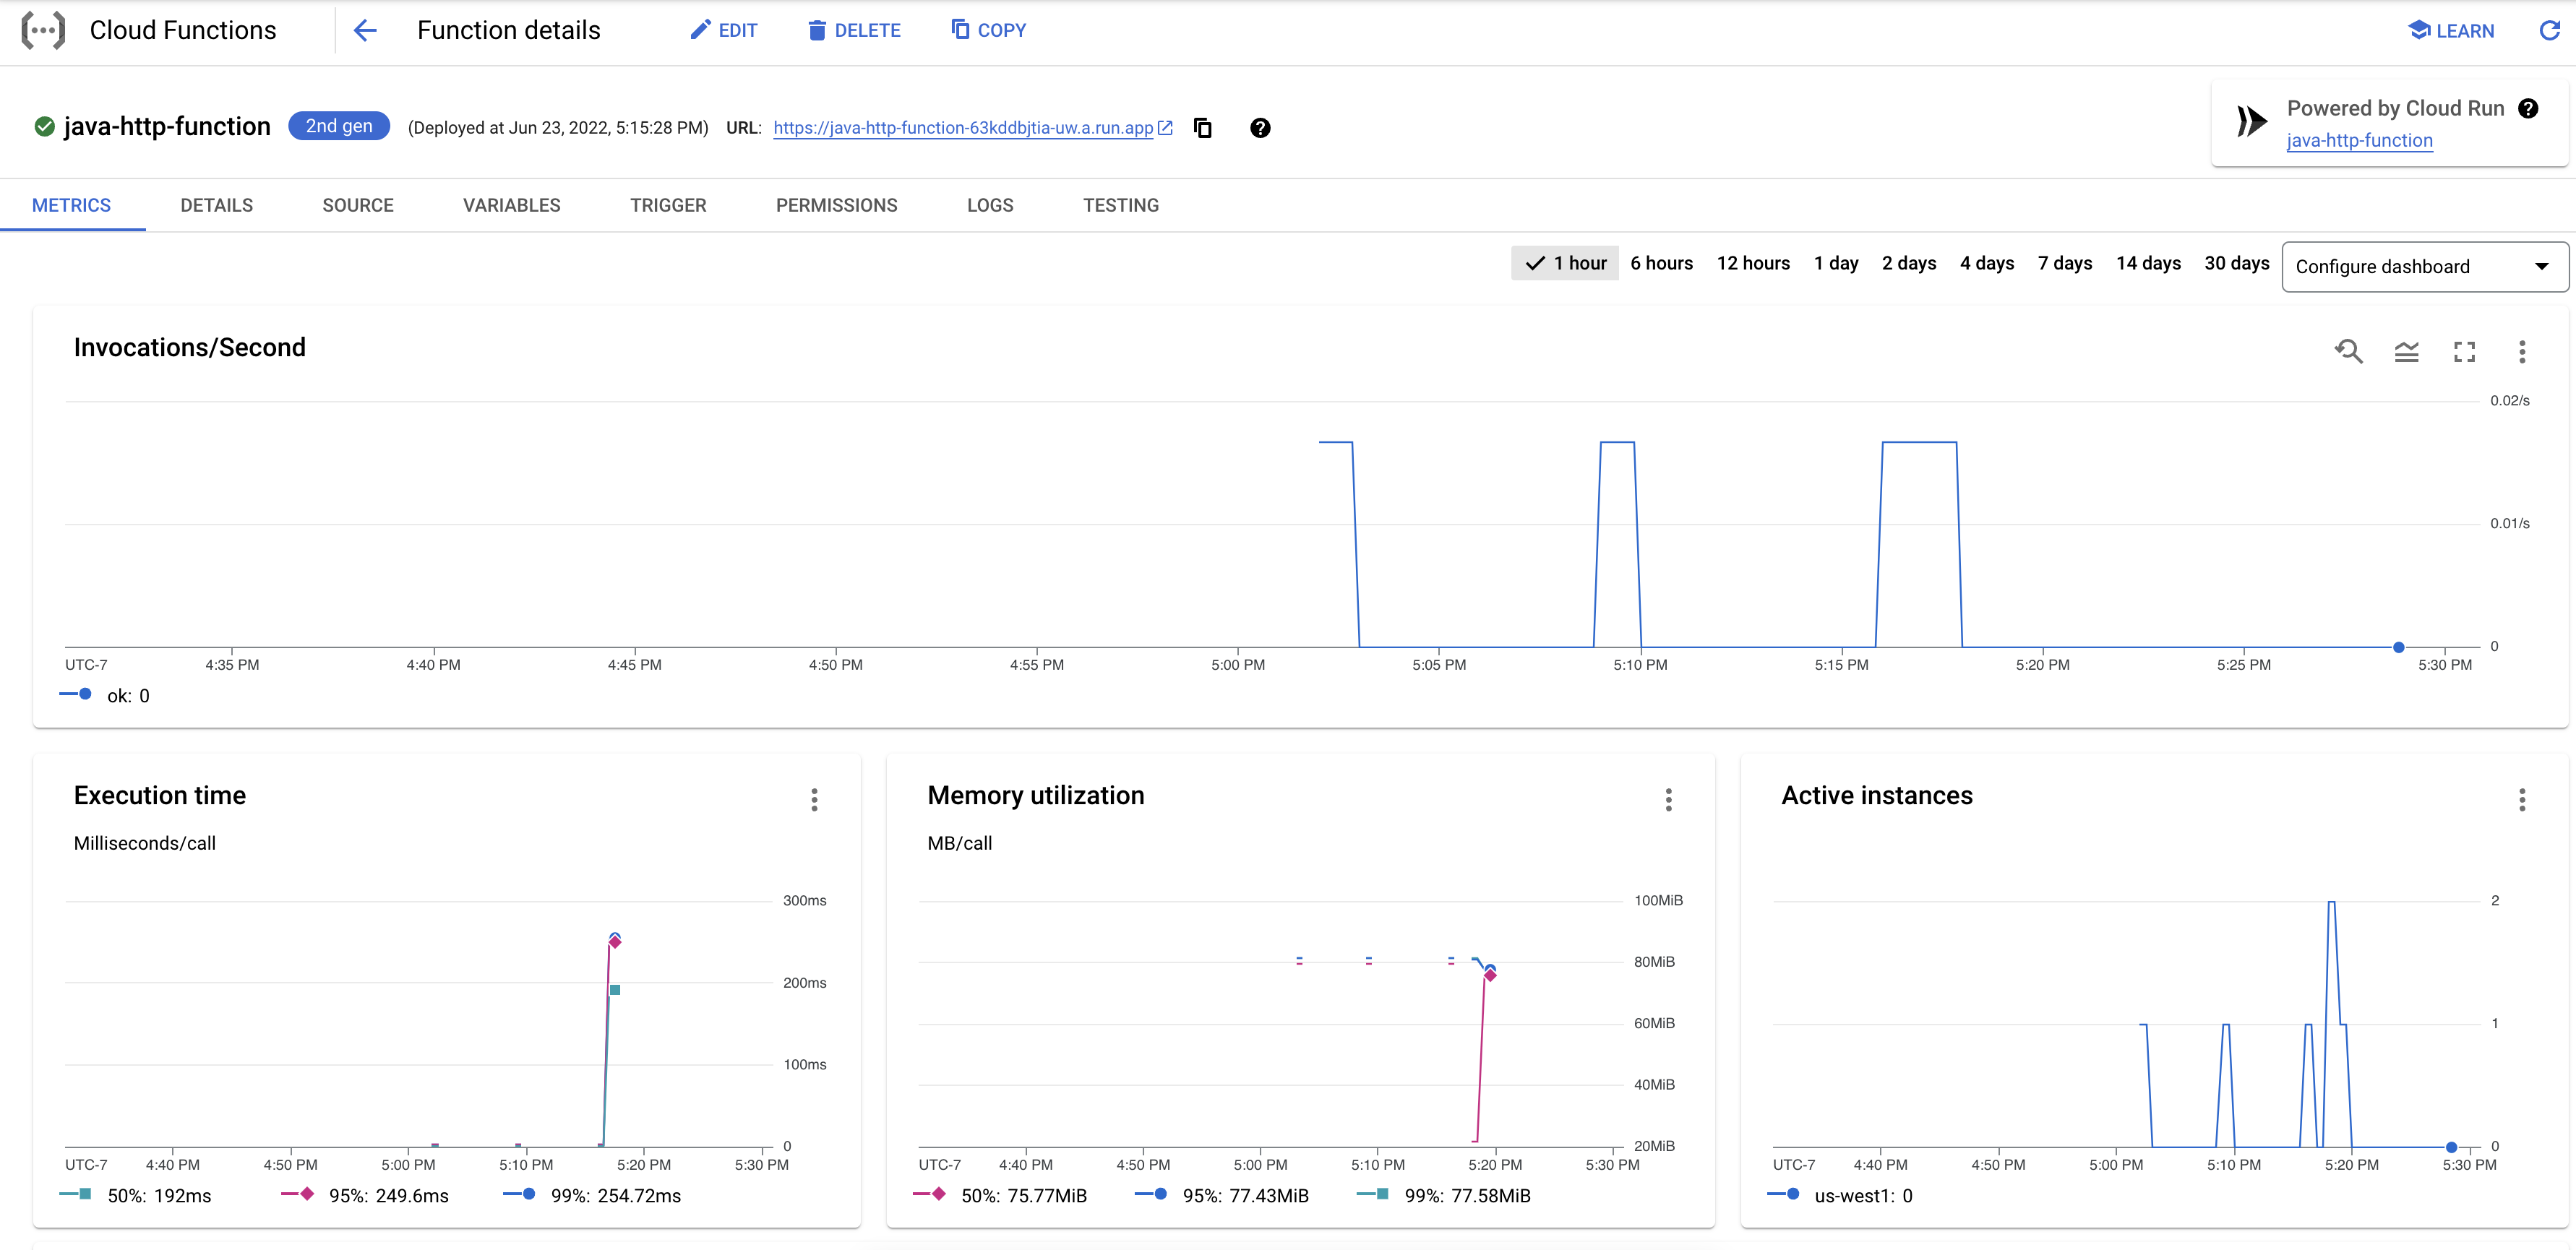
This is a bit of an exploration of what gets deployed into a GCP project, let’s start with the Cloud Function itself.


See how for a Gen2 function, a “Powered by Cloud Run” shows up which links to the actual cloud run deployment that powers this cloud function, clicking through leads to:


Conclusion

This concludes the steps to deploy a simple Java based Gen2 Cloud Function that responds to http calls. The post shows how the Gen 2 Cloud Function is more or less a pass through to Cloud Run. The sample is available in my github repository — https://github.com/bijukunjummen/http-cloudfunction-java-gradle


Saturday, May 14, 2022

Google Cloud Structured Logging for Java Applications

 One advice for logging that I have seen when targeting applications to cloud platforms is to simply write to Standard Out and platform takes care of sending it to the appropriate log sinks. This mostly works except when it doesn't - it especially doesn't when analyzing failure scenarios. Typically for Java applications this means looking through a stack trace and each line of a stack trace is treated as a separate log entry by the log sinks, this creates these problems:

  1. Correlating multiple line of output as being part of a single stack trace
  2. Since applications are multi-threaded even related logs may not be in just the right order
  3. The severity of logs is not correctly determined and so does not find its way into the Error Reporting system

This post will go into a few approaches when logging from a Java application in Google Cloud Platform


Problem

Let me go over the problem once more, so say I were to log the following way in Java code:

  LOGGER.info("Hello Logging") 
  

And it shows up the following way in the GCP Logging console

{
  "textPayload": "2022-04-29 22:00:12.057  INFO 1 --- [or-http-epoll-1] org.bk.web.GreetingsController           : Hello Logging",
  "insertId": "626c5fec0000e25a9b667889",
  "resource": {
    "type": "cloud_run_revision",
    "labels": {
      "service_name": "hello-cloud-run-sample",
      "configuration_name": "hello-cloud-run-sample",
      "project_id": "biju-altostrat-demo",
      "revision_name": "hello-cloud-run-sample-00008-qow",
      "location": "us-central1"
    }
  },
  "timestamp": "2022-04-29T22:00:12.057946Z",
  "labels": {
    "instanceId": "instanceid"
  },
  "logName": "projects/myproject/logs/run.googleapis.com%2Fstdout",
  "receiveTimestamp": "2022-04-29T22:00:12.077339403Z"
}
  

This looks reasonable. Now consider the case of logging in case of an error:

{
  "textPayload": "\t\tat reactor.core.publisher.Operators$MultiSubscriptionSubscriber.onSubscribe(Operators.java:2068) ~[reactor-core-3.4.17.jar:3.4.17]",
  "insertId": "626c619b00005956ab868f3f",
  "resource": {
    "type": "cloud_run_revision",
    "labels": {
      "revision_name": "hello-cloud-run-sample-00008-qow",
      "project_id": "biju-altostrat-demo",
      "location": "us-central1",
      "configuration_name": "hello-cloud-run-sample",
      "service_name": "hello-cloud-run-sample"
    }
  },
  "timestamp": "2022-04-29T22:07:23.022870Z",
  "labels": {
    "instanceId": "0067430fbd3ad615324262b55e1604eb6acbd21e59fa5fadd15cb4e033adedd66031dba29e1b81d507872b2c3c6cd58a83a7f0794965f8c5f7a97507bb5b27fb33"
  },
  "logName": "projects/biju-altostrat-demo/logs/run.googleapis.com%2Fstdout",
  "receiveTimestamp": "2022-04-29T22:07:23.317981870Z"
}

There would be multiple of these in the GCP logging console, for each line of the stack trace with no way to correlate them together. Additionally, there is no severity attached to these event and so the error would not end up with Google Cloud Error Reporting service.

Configuring Logging

There are a few approaches to configuring logging for a Java application targeted to be deployed to Google Cloud. The simplest approach, if using Logback, is to use the Logging appender provided by Google Cloud available here - https://github.com/googleapis/java-logging-logback.

Adding the appender is easy, a logback.xml file with the appender configured looks like this:

<configuration>
    <appender name="gcpLoggingAppender" class="com.google.cloud.logging.logback.LoggingAppender">
    </appender>
    <root level="INFO">
        <appender-ref ref="gcpLoggingAppender"/>
    </root>
</configuration>
This works great, but it has a huge catch. It requires connectivity to a GCP environment as it writes the logs directly to Cloud Logging system, which is not ideal for local testing. 

An approach that works when running in a GCP environment as well as locally is to simply direct the output to Standard Out, this will ensure that the logs are written in a json structured format and shipped correctly to Cloud Logging.
<configuration>
    <appender name="gcpLoggingAppender" class="com.google.cloud.logging.logback.LoggingAppender">
        <redirectToStdout>true</redirectToStdout>
    </appender>
    <root level="INFO">
        <appender-ref ref="gcpLoggingAppender"/>
    </root>
</configuration>
If you are using Spring Boot as the framework, the approach can be even be customized such that on a local environment the logs get written to Standard Out in a line by line manner, and when deployed to GCP, the logs are written as Json output:
<configuration>
    <include resource="org/springframework/boot/logging/logback/defaults.xml"/>
    <include resource="org/springframework/boot/logging/logback/console-appender.xml"/>

    <appender name="gcpLoggingAppender" class="com.google.cloud.logging.logback.LoggingAppender">
        <redirectToStdout>true</redirectToStdout>
    </appender>

    <root level="INFO">
        <springProfile name="gcp">
            <appender-ref ref="gcpLoggingAppender"/>
        </springProfile>
        <springProfile name="local">
            <appender-ref ref="CONSOLE"/>
        </springProfile>
    </root>
</configuration>  
  

This Works..But

Google Cloud logging appender works great, however there is an issue. It doesn't capture the entirety of a stack trace for some reason. I have an issue open which should address this. In the meantime if capturing the full stack in the logs is important then a different approach is to simply write a json formatted log using the native json layout provided by logback:

<appender name="jsonLoggingAppender" class="ch.qos.logback.core.ConsoleAppender">
    <layout class="ch.qos.logback.contrib.json.classic.JsonLayout">
        <jsonFormatter class="ch.qos.logback.contrib.jackson.JacksonJsonFormatter">
        </jsonFormatter>
        <timestampFormat>yyyy-MM-dd HH:mm:ss.SSS</timestampFormat>
        <appendLineSeparator>true</appendLineSeparator>
    </layout>
</appender> 
  
The fields however does not match the structured log format recommended by GCP, especially the severity, a quick tweak can be made by implementing a custom JsonLayout class that looks like this:

package org.bk.logback.custom;

import ch.qos.logback.classic.Level;
import ch.qos.logback.classic.spi.ILoggingEvent;
import ch.qos.logback.contrib.json.classic.JsonLayout;
import com.google.cloud.logging.Severity;

import java.util.Map;

public class GcpJsonLayout extends JsonLayout {
    private static final String SEVERITY_FIELD = "severity";

    @Override
    protected void addCustomDataToJsonMap(Map<String, Object> map, ILoggingEvent event) {
        map.put(SEVERITY_FIELD, severityFor(event.getLevel()));
    }

    private static Severity severityFor(Level level) {
        return switch (level.toInt()) {
            // TRACE
            case 5000 -> Severity.DEBUG;
            // DEBUG
            case 10000 -> Severity.DEBUG;
            // INFO
            case 20000 -> Severity.INFO;
            // WARNING
            case 30000 -> Severity.WARNING;
            // ERROR
            case 40000 -> Severity.ERROR;
            default -> Severity.DEFAULT;
        };
    }
}

which takes care of mapping to the right Severity levels for Cloud Error reporting. 

Conclusion

Use Google Cloud Logback appender and you should be set. Consider the alternate approaches only if you think you are lacking more of the stacktrace.

Saturday, April 30, 2022

Calling Google Cloud Services in Java

If you want to call Google Cloud Services using a Java based codebase, then broadly there are two approaches to incorporating the client libraries in your code — the first, let’s call it a “direct” approach is to use the Google Cloud Client libraries available here, the second approach is to use a “wrapper”, Spring Cloud GCP libraries available here.

So given both these libraries which one should you use. My take is simple — if you have a Spring Boot based app likely Spring Cloud GCP should be the preferred approach else the “direct” libraries.


Using Pub/Sub Client libraries

The best way to see the two approaches in action is to use it for making a call — in this case to publish a message to Cloud Pubsub.
The kind of contract I am expecting to implement looks like this:

The “message” is a simple type and looks like this, represented as a Java record:


Given this, let’s start with the “direct” approach.

Direct Approach

The best way that I have found to get to the libraries is using this page — https://github.com/googleapis/google-cloud-java/, which in turn links to the client libraries for the specific GCP services, the cloud pub/sub one is here — https://github.com/googleapis/java-pubsub. I use gradle for my builds and to pull in pub/sub libs with gradle is done this way:


implementation platform('com.google.cloud:libraries-bom:25.1.0')
implementation('com.google.cloud:google-cloud-pubsub')
With the library pulled in, the code to publish a message looks like this:


The message is converted to a raw json and published to Cloud Pub/Sub which returns a ApiFuture type. I have previously covered how such a type can be converted to reactive types which is finally returned from the publishing code.

The “publisher” is created using a helper method:


Publisher publisher = Publisher.newBuilder("sampletopic").build();

Spring Cloud GCP Approach

The documentation for Spring Cloud GCP project is available here, first to pull in the dependencies, for a Gradle based project it looks like this:


dependencies {
   implementation 'com.google.cloud:spring-cloud-gcp-starter-pubsub'
}

dependencyManagement {
   imports {
      mavenBom "com.google.cloud:spring-cloud-gcp-dependencies:${springCloudGcpVersion}"
      mavenBom "org.springframework.cloud:spring-cloud-dependencies:${springCloudVersion}"
   }
}

With the right dependencies pulled in Spring Boot Auto-configuration comes into play and automatically creates a type called the PubSubTemplate with properties that can tweak configuration A code to publish a message to a topic using a PubSubTemplate looks like this:

Comparison


Given these two code snippets, these are some of the differences:
  • Spring Cloud GCP has taken care of a bunch of boiler plate around how to create a Publisher (and subscriber if listening to messages)
  • The PubSubTemplate provides simpler helper methods for publishing messages and for listening to messages, the return type which is ListenableFuture with PubSubTemplate can easily be transformed to reactive types unlike the ApiFuture return type
  • Testing with Spring Cloud GCP is much simpler as the Publisher needs to be tweaked extensively to work with an emulator and Spring Cloud GCP handles this complication under the covers

Conclusion

The conclusion for me is that Spring Cloud GCP is compelling, if a project is Spring Boot based then Spring Cloud GCP will fit in great and provides just the right level of abstraction in dealing with the Google Cloud API’s.
The snippets in this blog post doesn’t do justice to some of the complexities of the codebase, my github repo may help with a complete working codebase with both “direct” and Spring cloud GCP based code — https://github.com/bijukunjummen/gcp-pub-sub-sample

Saturday, March 5, 2022

Modeling one-to-many relation in Firestore, Bigtable, Spanner

I like working with services that need little to no provisioning effort — these are typically termed as Fully Managed services by different Providers.

The most provisioning effort is typically required for database systems, I remember having to operate a Cassandra cluster in a previous job and the amount of effort spent on provisioning, upkeep was far from trivial and I appreciated and empathized with the role of a Database administrator dearly during that time.

My objective in this post is to explore how a one-to-many relationship can be maintained in 3 managed database solutions on Google Cloud — Firestore, Bigtable and Spanner.

Data Model

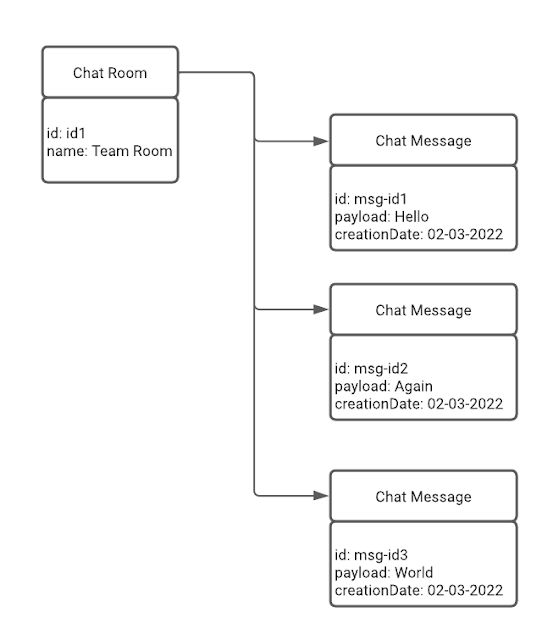
The data model is to represent a Chat Room with Chat Messages in the rooms.


Chat Room just has name as an attribute. Each Chat Room has a set of Chat Messages, with each message having a payload and creation date as attributes. A sample would look something like this:


So now comes the interesting question, how can this one-to-many relation be modeled using Firestore, Bigtable and Spanner. Let’s start with Firestore.

One-to-many using Firestore

Managing a One-to-many relation comes naturally to Firestore. The concepts map directly to the structures of Firestore:

  • Each Chat Room instance and each Chat Message can be thought of as a Firestore “Document”.
  • All the Chat Room instances are part of a “ChatRooms” “Collection”
  • Each Chat Room “Document” has a “Sub-Collection” to hold all the Chat Messages relevant to it, this way establishing a One-to-Many relationship


One-to-Many using Bigtable

A quick aside, in Bigtable information is stored in the following form


Each Chat Room and Chat Room message can be added in as rows with carefully crafted row keys.

  • A chat room, needs to be retrieved by its id, so a row key may look something like this: “ROOM/R#room-id”
  • Chat Room message row key can be something like this: “MESSAGES/R#chatroom-id/M#message-id”

Since Bigtable queries can be based on prefixes, a retrieval of messages by a prefix of “MESSAGES/R#chatroom-id” would retrieve all messages in the Chat Room “chatroom-id”. Not as intuitive as the Firestore structure as it requires carefully thinking about the row key structure.

One-to-Many using Spanner

Spanner behaves like a traditional relational database with a lot of smarts under the covers to scale massively. So for a one-to-many data model perspective, the relational concepts just carry over.

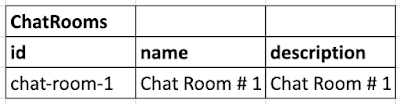
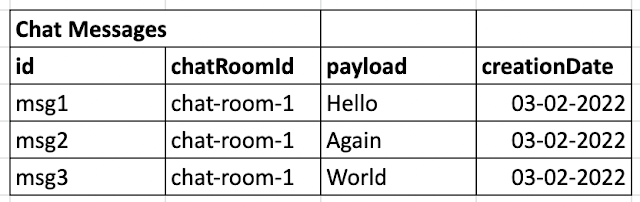
Chat Rooms can be stored in a “ChatRooms” table with the columns holding attributes of a chat room

Chat Messages can be stored in a “ChatMessages” table with columns holding the attributes of a chat message. A foreign key, say “ChatRoomId” in Chat Message can point to the relevant Chat Room.


Given this, all chat messages for a room can be retrieved using a query on Chat Messages with a filter on the Chat Room Id.

Conclusion

I hope this gives a taste of what it takes to model in these three excellent fully managed GCP databases.