Showing posts with label Spring-boot. Show all posts

Sunday, July 26, 2020

Backpressure in Project Reactor

Project Reactor implements the Reactive Streams specification, which is a standard for asynchronously processing a stream of data while respecting the processing capabilities of a consumer. 

At a very broad level, there are two entities involved, a Producer that produces the stream of data and a Consumer that consumes data. If the rate at which a Consumer consumes data is less than the rate at which a Producer produces data (referred to as a Fast Producer/Slow Consumer), then signals from the consumer can constrain the rate of production, this is referred to as Backpressure and in this post, I will be demonstrating a few backpressure examples using Project Reactor. 

Before I go ahead, I have to acknowledge that these examples are loosely based on what I learned from the "Reactive Programming with RxJava" book.

Producer

Flux in Project Reactor represents an asynchronous stream of 0..N data, where N can potentially be infinite. 

Consider a simple example, generating a sequence of numbers. There are built-in ways in Flux to do this, but for the example, I will be using an operator called Flux.generate. Sample code looks like this:
fun produce(targetRate: Int, upto: Long): Flux<Long> {
    val delayBetweenEmits: Long = 1000L / targetRate

    return Flux.generate(
        { 1L },
        { state: Long, sink: SynchronousSink<Long> ->
            sleep(delayBetweenEmits)
            val nextState: Long = state + 1
            if (state > upto) {
                sink.complete()
                nextState
            } else {
                LOGGER.info("Emitted {}", state)
                sink.next(state)
                nextState
            }
        }
    )
}

Here "targetRate" is the rate per second at which the Producer is expected to produce a sequence of numbers and "upto" represents the range for which the sequence is to be generated. "Thread.sleep" is used for introducing the delay between emissions.


Consumer

A consumer for this stream of data just consumes the sequence of numbers and to simulate processing while consuming the data, delays are again introduced just before reading the information, along these lines:
val delayBetweenConsumes: Long = 1000L / consumerRate
producer.produce(producerRate, count)
    .subscribe { value: Long ->
        sleep(delayBetweenConsumes)
        logger.info("Consumed {}", value)
    }

Just like with rate at the Producer side, there is a rate of consuming on the consumer side which drives the delay before consuming the data.


Scenario 1: Fast Producer, Slow Consumer without Threading

Now that I have a stream of data for which I can control the rate of production and rate of consumption, the first test that I ran was with the producer and the consumer chained together. 

The Producer produces at the rate of 100 requests a second and the consumer consuming it at 3 per second. 

If there were no backpressure mechanisms in place you would expect that Producer would merrily go along and produce all the records at its own pace of 100 per second and Consumer would slowly catch up at the rate of 3 per second.  This is NOT what happens though. 

The reason is not that intuitive I feel, it is not really backpressure coming into play either. The Producer is constrained to 3 requests per second merely because the entire flow from the Producer to the Consumer is synchronous by default and since the production and the consumption are happening on the same thread, the behavior is automatically constrained to what the Consumer is comfortable in consuming. 

Here is a graph which simply plots the rate of production and consumption over time and captures clearly the exact same rate of Production and Consumption throughout:


This behavior is borne out from the logs also, which show that the consumer and producer remain in sync:
2020-07-26 17:51:58.712  INFO 1 --- [pool-1-thread-1] sample.meter.Producer                    : Emitted 84
2020-07-26 17:51:59.048  INFO 1 --- [pool-1-thread-1] sample.meter.Consumer                    : Consumed 84
2020-07-26 17:51:59.059  INFO 1 --- [pool-1-thread-1] sample.meter.Producer                    : Emitted 85
2020-07-26 17:51:59.393  INFO 1 --- [pool-1-thread-1] sample.meter.Consumer                    : Consumed 85
2020-07-26 17:51:59.404  INFO 1 --- [pool-1-thread-1] sample.meter.Producer                    : Emitted 86
2020-07-26 17:51:59.740  INFO 1 --- [pool-1-thread-1] sample.meter.Consumer                    : Consumed 86
2020-07-26 17:51:59.751  INFO 1 --- [pool-1-thread-1] sample.meter.Producer                    : Emitted 87
2020-07-26 17:52:00.084  INFO 1 --- [pool-1-thread-1] sample.meter.Consumer                    : Consumed 87
2020-07-26 17:52:00.095  INFO 1 --- [pool-1-thread-1] sample.meter.Producer                    : Emitted 88
2020-07-26 17:52:00.430  INFO 1 --- [pool-1-thread-1] sample.meter.Consumer                    : Consumed 88
2020-07-26 17:52:00.441  INFO 1 --- [pool-1-thread-1] sample.meter.Producer                    : Emitted 89
2020-07-26 17:52:00.777  INFO 1 --- [pool-1-thread-1] sample.meter.Consumer                    : Consumed 89
2020-07-26 17:52:00.788  INFO 1 --- [pool-1-thread-1] sample.meter.Producer                    : Emitted 90
2020-07-26 17:52:01.087  INFO 1 --- [pool-1-thread-1] sample.meter.Consumer                    : Consumed 90
2020-07-26 17:52:01.097  INFO 1 --- [pool-1-thread-1] sample.meter.Producer                    : Emitted 91
2020-07-26 17:52:01.432  INFO 1 --- [pool-1-thread-1] sample.meter.Consumer                    : Consumed 91
2020-07-26 17:52:01.442  INFO 1 --- [pool-1-thread-1] sample.meter.Producer                    : Emitted 92
2020-07-26 17:52:01.777  INFO 1 --- [pool-1-thread-1] sample.meter.Consumer                    : Consumed 92
2020-07-26 17:52:01.788  INFO 1 --- [pool-1-thread-1] sample.meter.Producer                    : Emitted 93
2020-07-26 17:52:02.123  INFO 1 --- [pool-1-thread-1] sample.meter.Consumer                    : Consumed 93
2020-07-26 17:52:02.133  INFO 1 --- [pool-1-thread-1] sample.meter.Producer                    : Emitted 94
2020-07-26 17:52:02.467  INFO 1 --- [pool-1-thread-1] sample.meter.Consumer                    : Consumed 94
2020-07-26 17:52:02.478  INFO 1 --- [pool-1-thread-1] sample.meter.Producer                    : Emitted 95
2020-07-26 17:52:02.813  INFO 1 --- [pool-1-thread-1] sample.meter.Consumer                    : Consumed 95
2020-07-26 17:52:02.824  INFO 1 --- [pool-1-thread-1] sample.meter.Producer                    : Emitted 96
2020-07-26 17:52:03.157  INFO 1 --- [pool-1-thread-1] sample.meter.Consumer                    : Consumed 96
2020-07-26 17:52:03.168  INFO 1 --- [pool-1-thread-1] sample.meter.Producer                    : Emitted 97


Scenario 2: Fast Producer, Slow Consumer with Threading

The second scenario that I considered was with the Producer and the Consumer being produced independently in different threads. 

Project reactor makes this possible through two operators subscribeOn() which changes the thread where in my case the Producer produces the sequence and a publishOn() which shifts the consumption to a different thread. 

With these in place, the code looks like this:
producer.produce(producerRate, count)
    .subscribeOn(subscribeOnScheduler)
    .publishOn(publishOnScheduler)
    .subscribe { value: Long ->
        sleep(delayBetweenConsumes)
        logger.info("Consumed {}", value)
    }
The results were a little surprising, this is what I saw in the logs:
...
2020-07-26 18:42:41.774  INFO 1 --- [    subscribe-3] sample.meter.Producer                    : Emitted 252
2020-07-26 18:42:41.786  INFO 1 --- [    subscribe-3] sample.meter.Producer                    : Emitted 253
2020-07-26 18:42:41.797  INFO 1 --- [    subscribe-3] sample.meter.Producer                    : Emitted 254
2020-07-26 18:42:41.809  INFO 1 --- [    subscribe-3] sample.meter.Producer                    : Emitted 255
2020-07-26 18:42:41.819  INFO 1 --- [    subscribe-3] sample.meter.Producer                    : Emitted 256
2020-07-26 18:42:42.019  INFO 1 --- [      publish-2] sample.meter.Consumer                    : Consumed 9
2020-07-26 18:42:42.354  INFO 1 --- [      publish-2] sample.meter.Consumer                    : Consumed 10
2020-07-26 18:42:42.689  INFO 1 --- [      publish-2] sample.meter.Consumer                    : Consumed 11
2020-07-26 18:42:43.024  INFO 1 --- [      publish-2] sample.meter.Consumer                    : Consumed 12
2020-07-26 18:42:43.358  INFO 1 --- [      publish-2] sample.meter.Consumer                    : Consumed 13
2020-07-26 18:42:43.691  INFO 1 --- [      publish-2] sample.meter.Consumer                    : Consumed 14
2020-07-26 18:42:44.027  INFO 1 --- [      publish-2] sample.meter.Consumer                    : Consumed 15
2020-07-26 18:42:44.363  INFO 1 --- [      publish-2] sample.meter.Consumer                    : Consumed 16
.....
2020-07-26 18:43:43.724  INFO 1 --- [    subscribe-3] sample.meter.Producer                    : Emitted 299
2020-07-26 18:43:43.735  INFO 1 --- [    subscribe-3] sample.meter.Producer                    : Emitted 300
2020-07-26 18:43:43.913  INFO 1 --- [      publish-2] sample.meter.Consumer                    : Consumed 194
2020-07-26 18:43:44.248  INFO 1 --- [      publish-2] sample.meter.Consumer                    : Consumed 195
2020-07-26 18:43:44.581  INFO 1 --- [      publish-2] sample.meter.Consumer                    : Consumed 196
...
A sequence of numbers upto 256 was produced immediately and then the Producer waited for the Consumer to catch up, once the consumer caught up, the remaining emissions happened. This is how the graph for this looks: 


Clearly, backpressure is acting on this stream of data. The surprising aspect for me was the backpressure appeared to be triggering at a large value of 256 records from upstream.

Analyzing this is a little, the reason I realized is that an intermediate operation is buffering the requests. The intermediate operation in this instance happens to be the "publishOn()" operator that I am using, a variant of "publishOn()" which additionally takes in a prefetch parameter fixes the size of the buffer. 

In my case setting it to 10 felt reasonable, the code looks like this now:
producer.produce(producerRate, count)
    .subscribeOn(subscribeOnScheduler)
    .publishOn(publishOnScheduler, 10)
    .subscribe { value: Long ->
        sleep(delayBetweenConsumes)
        logger.info("Consumed {}", value)
    }
and the graph with the Producer and Consumer remains closely in sync:

Producer In Green, Consumer in Red


Scenario 3: Fast Producer, Multi-threaded Consumer

If you look closely at the name of the threads in logs from the first two scenarios then you would notice that the names of the thread at the point of production and at the point of consumption are always the same. The operators "publishOn()" and "subscribeOn()" don't parallelize the operation, they only switch the execution context of the operations. To really parallelize the operations, two approaches can be taken: 

  1. Using the parallel operator 
  2. Using flatMap flavors with their own "subscribeOn" operators 

For the 3rd scenario, I went for the second option of using flatMap and it looks something like this:
producer.produce(producerRate, count)
    .subscribeOn(subscribeOnScheduler)
    .publishOn(publishOnScheduler, 10)
    .flatMap({ value: Long ->
        Mono.fromSupplier {
            sleep(delayBetweenConsumes)
            logger.info("Consumed {}", value)
            null
        }.subscribeOn(flatMapScheduler)
    }, concurrency)
    .subscribe()
The work of consuming the produced sequence of numbers is being done inside the flatMap operation, the number of concurrent consumption is set to 5 by default. Running this scenario produces the following logs, the consumers are now running 5 at a time on multiple threads:
2020-07-26 23:26:27.212  INFO 1 --- [    subscribe-3] sample.meter.Producer                    : Emitted 1
2020-07-26 23:26:27.321  INFO 1 --- [    subscribe-3] sample.meter.Producer                    : Emitted 2
2020-07-26 23:26:27.423  INFO 1 --- [    subscribe-3] sample.meter.Producer                    : Emitted 3
...
2020-07-26 23:26:28.040  INFO 1 --- [    subscribe-3] sample.meter.Producer                    : Emitted 9
2020-07-26 23:26:28.143  INFO 1 --- [    subscribe-3] sample.meter.Producer                    : Emitted 10
2020-07-26 23:26:28.222  INFO 1 --- [      flatMap-4] sample.meter.Consumer                    : Consumed 1
2020-07-26 23:26:28.328  INFO 1 --- [      flatMap-5] sample.meter.Consumer                    : Consumed 2
2020-07-26 23:26:28.428  INFO 1 --- [      flatMap-6] sample.meter.Consumer                    : Consumed 3
2020-07-26 23:26:28.527  INFO 1 --- [      flatMap-7] sample.meter.Consumer                    : Consumed 4
...
The rate of production lines up with the rate of consumption

Producer In Green/Consumer in Red


Conclusion

These are different experiments that I was able to run to simulate backpressure scenarios with Project Reactor and the behavior should be true for most Reactive Streams based libraries. 

Project Reactor has sane defaults in managing the backpressure needs of a Consumer and provides ways to override the defaults. 

In all scenarios that I have run in this post, the Producer throttled the production to a rate that the Consumer was comfortable in consuming. 

 If you are interested in exploring the scenarios further, my codebase along with the grafana/prometheus set up for graphing the output is available in my github repository here - https://github.com/bijukunjummen/backpressure-demo

Sunday, March 22, 2020

Processing SQS Messages using Spring Boot and Project Reactor

I recently worked on a project where I had to efficiently process a large number of messages streaming in through an AWS SQS Queue. In this post (and potentially one more), I will go over the approach that I took to process the messages using the excellent Project Reactor


The following is the kind of set-up that I am aiming for:


Setting up a local AWS Environment

Before I jump into the code, let me get some preliminaries out of the way. First, how do you get a local version of SNS and SQS. One of the easiest ways is to use localstack. I use a docker-compose version of it described here

The second utility that I will be using is the AWS CLI. This website has details on how to install it locally.

Once both of these utilities are in place, a quick test should validate the setup:

# Create a queue
aws --endpoint http://localhost:4576 sqs create-queue --queue-name test-queue

# Send a sample message
aws --endpoint http://localhost:4576 sqs send-message --queue-url http://localhost:4576/queue/test-queue --message-body "Hello world"

# Receive the message
aws --endpoint http://localhost:4576 sqs receive-message --queue-url http://localhost:4576/queue/test-queue


Basics of Project Reactor


Project Reactor implements the Reactive Streams specification and provides a way of handling streams of data across asynchronous boundaries that respects backpressure. A lot of words here but in essence think of it this way:
1. SQS Produces data
2. The application is going to consume and process it as a stream of data
3. The application should consume data at a pace that is sustainable - too much data should not be pumped in. This is formally referred to as "Backpressure"


AWS SDK 2

The library that I will be using to consume AWS SQS data is the AWS SDK 2. The library uses non-blocking IO under the covers.

The library offers both a sync version of making calls as well as an async version. Consider the synchronous way to fetch records from an SQS queue:

import software.amazon.awssdk.services.sqs.model.ReceiveMessageRequest
import software.amazon.awssdk.services.sqs.SqsClient

val receiveMessageRequest: ReceiveMessageRequest = ReceiveMessageRequest.builder()
    .queueUrl(queueUrl)
    .maxNumberOfMessages(5)
    .waitTimeSeconds(10)
    .build()

val messages: List<Message> = sqsClient.receiveMessage(receiveMessageRequest).messages()

Here "software.amazon.awssdk.services.sqs.SqsClient" is being used for querying sqs and retrieving a batch of results synchronously. An async result, on the other hand, looks like this:


val receiveMessageRequest: ReceiveMessageRequest = ReceiveMessageRequest.builder()
    .queueUrl(queueUrl)
    .maxNumberOfMessages(5)
    .waitTimeSeconds(10)
    .build()

val messages: CompletableFuture<List<Message>> = sqsAsyncClient
    .receiveMessage(receiveMessageRequest)
    .thenApply { result -> result.messages() }


The output now is now a "CompletableFuture"

Infinite loop and no backpressure

My first attempt at creating a stream(Flux) of message is fairly simple - an infinite loop that polls AWS sqs and creates a Flux from it using the "Flux.create" operator, this way:

fun listen(): Flux<Pair<String, () -> Unit>> {
    return Flux.create { sink: FluxSink<List<Message>> ->
            while (running) {
                try {
                    val receiveMessageRequest: ReceiveMessageRequest = ReceiveMessageRequest.builder()
                        .queueUrl(queueUrl)
                        .maxNumberOfMessages(5)
                        .waitTimeSeconds(10)
                        .build()

                    val messages: List<Message> = sqsClient.receiveMessage(receiveMessageRequest).messages()
                    LOGGER.info("Received: $messages")
                    sink.next(messages)
                } catch (e: InterruptedException) {
                    LOGGER.error(e.message, e)
                } catch (e: Exception) {
                    LOGGER.error(e.message, e)
                }
            }
        }
        .flatMapIterable(Function.identity())
        .doOnError { t: Throwable -> LOGGER.error(t.message, t) }
        .retry()
        .map { snsMessage: Message ->
            val snsMessageBody: String = snsMessage.body()
            val snsNotification: SnsNotification = readSnsNotification(snsMessageBody)
            snsNotification.message to { deleteQueueMessage(snsMessage.receiptHandle(), queueUrl) }
        }
}

The way this works is that there is an infinite loop that checks for new messages using long-polling. Messages may not be available at every poll, in which case an empty list is added to the stream.

This list of atmost 5 messages is then mapped to a stream of individual messages using the "flatMapIterable" operator, which is further mapped by extracting the message from the SNS wrapper (as message gets forwarded from SNS to SQS, SNS adds a wrapper to the message) and a way to delete the message(deleteHandle) once the message is successfully processed is returned as Pair.


This approach works perfectly fine... but imagine a case where a huge number of messages have come in, since the loop is not really aware of the throughput downstream it will keep pumping data to the stream. The default behavior is for the intermediate operators to buffer this data flowing in based on how the final consumer is consuming the data. Since this buffer is unbounded it is possible that the system may reach an unsustainable state.


Backpressure aware stream

The fix is to use a different operator to generate the stream of data - Flux.generate.
Using this operator the code looks like this:

fun listen(): Flux<Pair<String, () -> Unit>> {
    return Flux.generate { sink: SynchronousSink<List<Message>> ->
            val receiveMessageRequest: ReceiveMessageRequest = ReceiveMessageRequest.builder()
                .queueUrl(queueUrl)
                .maxNumberOfMessages(5)
                .waitTimeSeconds(10)
                .build()

            val messages: List<Message> = sqsClient.receiveMessage(receiveMessageRequest).messages()
            LOGGER.info("Received: $messages")
            sink.next(messages)
        }
        .flatMapIterable(Function.identity())
        .doOnError { t: Throwable -> LOGGER.error(t.message, t) }
        .retry()
        .map { snsMessage: Message ->
            val snsMessageBody: String = snsMessage.body()
            val snsNotification: SnsNotification = readSnsNotification(snsMessageBody)
            snsNotification.message to { deleteQueueMessage(snsMessage.receiptHandle(), queueUrl) }
        }
}

The way this works is that the block passed to the "Flux.generate" operator is repeatedly called - similar to the while loop, in each loop one item is expected to be added to the stream. In this instance, the item added to the stream happens to be a list which like before is broken down into individual messages.

How does backpressure work in this scenario -
So again consider the case where the downstream consumer is processing at a slower rate than the generating end. In this case, Flux itself would slow down at the rate at which the generate operator is called, thus being considerate of the throughput of the downstream system.

Conclusion

This should set up a good pipeline for processing messages from SQS, there are a few more nuances to this to process messages in parallel later in the stream which I will cover in a future post.

The codebase of this example is available in my github repository here - https://github.com/bijukunjummen/boot-with-sns-sqs. The code has a complete pipeline which includes processing the message and deleting it once processed.

Monday, January 20, 2020

Spring WebClient and Java date-time fields

WebClient is Spring Framework's reactive client for making service to service calls.

WebClient has become a go to utility for me, however I unexpectedly encountered an issue recently in the way it handles Java 8 time fields that tripped me up and this post goes into the details.


Happy Path

First the happy path. When using a WebClient, Spring Boot advices a "WebClient.Builder" to be injected into a class instead of the "WebClient" itself and a WebClient.Builder is already auto-configured and available for injection.


Consider a fictitious "City" domain and a client to create a "City". "City" has a simple structure, note that the creationDate is a Java8 "Instant" type:

import java.time.Instant

data class City(
    val id: Long,
    val name: String,
    val country: String,
    val pop: Long,
    val creationDate: Instant = Instant.now()
)

The client to create an instance of this type looks like this:

class CitiesClient(
    private val webClientBuilder: WebClient.Builder,
    private val citiesBaseUrl: String
) {
    fun createCity(city: City): Mono<City> {
        val uri: URI = UriComponentsBuilder
            .fromUriString(citiesBaseUrl)
            .path("/cities")
            .build()
            .encode()
            .toUri()

        val webClient: WebClient = this.webClientBuilder.build()

        return webClient.post()
            .uri(uri)
            .contentType(MediaType.APPLICATION_JSON)
            .accept(MediaType.APPLICATION_JSON)
            .bodyValue(city)
            .exchange()
            .flatMap { clientResponse ->
                clientResponse.bodyToMono(City::class.java)
            }
    }
}

See how the intent is expressed in a fluent way. The uri and the headers are first being set, the request body is then put in place and the response is unmarshalled back to a "City" response type.


All well and good. Now how does a test look like.

I am using the excellent Wiremock to bring up a dummy remote service and using this CitiesClient to send the request, along these lines:

@SpringBootTest 
@AutoConfigureJson
class WebClientConfigurationTest {

    @Autowired
    private lateinit var webClientBuilder: WebClient.Builder

    @Autowired
    private lateinit var objectMapper: ObjectMapper

    @Test
    fun testAPost() {
        val dateAsString = "1985-02-01T10:10:10Z"

        val city = City(
            id = 1L, name = "some city",
            country = "some country",
            pop = 1000L,
            creationDate = Instant.parse(dateAsString)
        )
        WIREMOCK_SERVER.stubFor(
            post(urlMatching("/cities"))
                .withHeader("Accept", equalTo("application/json"))
                .withHeader("Content-Type", equalTo("application/json"))
                .willReturn(
                    aResponse()
                        .withHeader("Content-Type", "application/json")
                        .withStatus(HttpStatus.CREATED.value())
                        .withBody(objectMapper.writeValueAsString(city))
                )
        )

        val citiesClient = CitiesClient(webClientBuilder, "http://localhost:${WIREMOCK_SERVER.port()}")

        val citiesMono: Mono<City> = citiesClient.createCity(city)

        StepVerifier
            .create(citiesMono)
            .expectNext(city)
            .expectComplete()
            .verify()


        //Ensure that date field is in ISO-8601 format..
        WIREMOCK_SERVER.verify(
            postRequestedFor(urlPathMatching("/cities"))
                .withRequestBody(matchingJsonPath("$.creationDate", equalTo(dateAsString)))
        )
    }

    companion object {
        private val WIREMOCK_SERVER =
            WireMockServer(WireMockConfiguration.wireMockConfig().dynamicPort().notifier(ConsoleNotifier(true)))

        @BeforeAll
        @JvmStatic
        fun beforeAll() {
            WIREMOCK_SERVER.start()
        }

        @AfterAll
        @JvmStatic
        fun afterAll() {
            WIREMOCK_SERVER.stop()
        }
    }
}

In the highlighted lines, I want to make sure that the remote service receives the date in ISO-8601 format as "1985-02-01T10:10:10Z". In this instance everything works cleanly and the test passes.

Not so happy path

Consider now a case where I have customized the WebClient.Builder in some form. An example is say I am using a registry service and I want to look up a remote service via this registry and then make a call then the WebClient has to be customized to add a "@LoadBalanced" annotation on it - some details here

So say, I have customized WebClient.Builder this way:

@Configuration
class WebClientConfiguration {

    @Bean
    fun webClientBuilder(): WebClient.Builder {
        return WebClient.builder().filter { req, next ->
            LOGGER.error("Custom filter invoked..")
            next.exchange(req)
        }
    }

    companion object {
        val LOGGER = loggerFor<WebClientConfiguration>()
    }
}

It looks straightforward, however now the previous test fails. Specifically the date format of the creationDate over the wire is not ISO-8601 anymore, the raw request looks like this:

{
    "id": 1,
    "name": "some city",
    "country": "some country",
    "pop": 1000,
    "creationDate": 476100610.000000000
}

vs for a working request:

{
    "id": 1,
    "name": "some city",
    "country": "some country",
    "pop": 1000,
    "creationDate": "1985-02-01T10:10:10Z"
}

See how the date format is different.

Problem

The underlying reason for this issue is simple, Spring Boot adds a bunch of configuration on WebClient.Builder that is lost when I have explicitly created the bean myself. Specifically in this instance there is a Jackson ObjectMapper created under the covers which by default writes dates as timestamps - some details here.

Solution

Okay, so how do we get back the customizations that Spring Boot makes. I have essentially replicated the behavior of a auto-configuration in Spring called "WebClientAutoConfiguration" and it looks like this:

@Configuration
class WebClientConfiguration {

    @Bean
    fun webClientBuilder(customizerProvider: ObjectProvider<WebClientCustomizer>): WebClient.Builder {
        val webClientBuilder: WebClient.Builder = WebClient
            .builder()
            .filter { req, next ->
                LOGGER.error("Custom filter invoked..")
                next.exchange(req)
            }

        customizerProvider.orderedStream()
            .forEach { customizer -> customizer.customize(webClientBuilder) }

        return webClientBuilder;
    }

    companion object {
        val LOGGER = loggerFor<WebClientConfiguration>()
    }
}

There is a likely a better approach than just replicating this behavior, but this approach works for me.

The posted content now looks like this:

{
    "id": 1,
    "name": "some city",
    "country": "some country",
    "pop": 1000,
    "creationDate": "1985-02-01T10:10:10Z"
}

with the date back in the right format.

Conclusion

Spring Boot's auto-configurations for WebClient provides a opinionated set of defaults. If for any reason the WebClient and it's builder need to be configured explicitly then be wary of some of the customizations that Spring Boot adds and replicate it for the customized bean. In my case, the Jackson customization for Java 8 dates was missing in my custom "WebClient.Builder" and had to be explicitly accounted for.

A sample test and a customization is available here

Sunday, September 15, 2019

Unit test for Spring's WebClient

WebClient to quote its Java documentation is Spring Framework's
Non-blocking, reactive client to perform HTTP requests, exposing a fluent, reactive API over underlying HTTP client libraries such as Reactor Netty
.

In my current project I have been using WebClient extensively in making service to service calls and have found it to be an awesome API and I love its use of fluent interface.

Consider a remote service which returns a list of "Cities". A code using WebClient looks like this:

...
import org.springframework.http.MediaType
import org.springframework.web.reactive.function.client.WebClient
import org.springframework.web.reactive.function.client.bodyToFlux
import org.springframework.web.util.UriComponentsBuilder
import reactor.core.publisher.Flux
import java.net.URI

class CitiesClient(
        private val webClientBuilder: WebClient.Builder,
        private val citiesBaseUrl: String
) {

    fun getCities(): Flux<City> {
        val buildUri: URI = UriComponentsBuilder
                .fromUriString(citiesBaseUrl)
                .path("/cities")
                .build()
                .encode()
                .toUri()

        val webClient: WebClient = this.webClientBuilder.build()

        return webClient.get()
                .uri(buildUri)
                .accept(MediaType.APPLICATION_JSON)
                .exchange()
                .flatMapMany { clientResponse ->
                    clientResponse.bodyToFlux<City>()
                }
    }
}

It is difficult to test a client making use of WebClient though. In this post, I will go over the challenges in testing a client using WebClient and a clean solution.

Challenges in mocking WebClient

An effective unit test of the "CitiesClient" class would require mocking of WebClient and every method call in the fluent interface chain along these lines:

val mockWebClientBuilder: WebClient.Builder = mock()
val mockWebClient: WebClient = mock()
whenever(mockWebClientBuilder.build()).thenReturn(mockWebClient)

val mockRequestSpec: WebClient.RequestBodyUriSpec = mock()
whenever(mockWebClient.get()).thenReturn(mockRequestSpec)
val mockRequestBodySpec: WebClient.RequestBodySpec = mock()

whenever(mockRequestSpec.uri(any<URI>())).thenReturn(mockRequestBodySpec)

whenever(mockRequestBodySpec.accept(any())).thenReturn(mockRequestBodySpec)

val citiesJson: String = this.javaClass.getResource("/sample-cities.json").readText()

val clientResponse: ClientResponse = ClientResponse
        .create(HttpStatus.OK)
        .header("Content-Type","application/json")
        .body(citiesJson).build()

whenever(mockRequestBodySpec.exchange()).thenReturn(Mono.just(clientResponse))

val citiesClient = CitiesClient(mockWebClientBuilder, "http://somebaseurl")

val cities: Flux<City> = citiesClient.getCities()

This makes for an extremely flaky test as any change in the order of calls would result in new mocks that will need to be recorded.

Testing using real endpoints


An approach that works well is to bring up a real server that behaves like the target of a client. Two mock servers that work really well are mockwebserver in okhttp library and WireMock. An example with Wiremock looks like this:

import com.github.tomakehurst.wiremock.WireMockServer
import com.github.tomakehurst.wiremock.client.WireMock
import com.github.tomakehurst.wiremock.core.WireMockConfiguration
import org.bk.samples.model.City
import org.junit.jupiter.api.AfterAll
import org.junit.jupiter.api.BeforeAll
import org.junit.jupiter.api.Test
import org.springframework.http.HttpStatus
import org.springframework.web.reactive.function.client.WebClient
import reactor.core.publisher.Flux
import reactor.test.StepVerifier

class WiremockWebClientTest {

    @Test
    fun testARemoteCall() {
        val citiesJson = this.javaClass.getResource("/sample-cities.json").readText()
        WIREMOCK_SERVER.stubFor(WireMock.get(WireMock.urlMatching("/cities"))
                .withHeader("Accept", WireMock.equalTo("application/json"))
                .willReturn(WireMock.aResponse()
                        .withStatus(HttpStatus.OK.value())
                        .withHeader("Content-Type", "application/json")
                        .withBody(citiesJson)))

        val citiesClient = CitiesClient(WebClient.builder(), "http://localhost:${WIREMOCK_SERVER.port()}")

        val cities: Flux<City> = citiesClient.getCities()
        
        StepVerifier
                .create(cities)
                .expectNext(City(1L, "Portland", "USA", 1_600_000L))
                .expectNext(City(2L, "Seattle", "USA", 3_200_000L))
                .expectNext(City(3L, "SFO", "USA", 6_400_000L))
                .expectComplete()
                .verify()
    }

    companion object {
        private val WIREMOCK_SERVER = WireMockServer(WireMockConfiguration.wireMockConfig().dynamicPort())

        @BeforeAll
        @JvmStatic
        fun beforeAll() {
            WIREMOCK_SERVER.start()
        }

        @AfterAll
        @JvmStatic
        fun afterAll() {
            WIREMOCK_SERVER.stop()
        }
    }
}

Here a server is being brought up at a random port, it is then injected with a behavior and then the client is tested against this server and validated. This approach works and there is no muddling with the internals of WebClient in mocking this behavior, but technically this is an integration test and it will be slower to execute than a pure unit test.


Unit testing by short-circuiting the remote call

An approach that I have been using recently is to short circuit the remote call using an ExchangeFunction. An ExchangeFunction represents the actual mechanisms in making the remote call and can be replaced with one that responds with what the test expects the following way:

import org.junit.jupiter.api.Test
import org.springframework.http.HttpStatus
import org.springframework.web.reactive.function.client.ClientResponse
import org.springframework.web.reactive.function.client.ExchangeFunction
import org.springframework.web.reactive.function.client.WebClient
import reactor.core.publisher.Flux
import reactor.core.publisher.Mono
import reactor.test.StepVerifier

class CitiesWebClientTest {

    @Test
    fun testCleanResponse() {
        val citiesJson: String = this.javaClass.getResource("/sample-cities.json").readText()

        val clientResponse: ClientResponse = ClientResponse
                .create(HttpStatus.OK)
                .header("Content-Type","application/json")
                .body(citiesJson).build()
        val shortCircuitingExchangeFunction = ExchangeFunction {
            Mono.just(clientResponse)
        }

        val webClientBuilder: WebClient.Builder = WebClient.builder().exchangeFunction(shortCircuitingExchangeFunction)
        val citiesClient = CitiesClient(webClientBuilder, "http://somebaseurl")

        val cities: Flux<City> = citiesClient.getCities()

        StepVerifier
                .create(cities)
                .expectNext(City(1L, "Portland", "USA", 1_600_000L))
                .expectNext(City(2L, "Seattle", "USA", 3_200_000L))
                .expectNext(City(3L, "SFO", "USA", 6_400_000L))
                .expectComplete()
                .verify()
    }
}

The WebClient is injected with a ExchangeFunction which simply returns a response with the expected behavior of the remote server. This has short circuited the entire remote call and allows the client to be tested comprehensively. This approach depends on a little knowledge of the internals of the WebClient. This is a decent compromise though as it would run far faster than a test using WireMock.

This approach is not original though, I have based this test on some of the tests used for testing WebClient itself, for eg, the one here


Conclusion

I personally prefer the last approach, it has enabled me to write fairly comprehensive unit tests for a Client making use of WebClient for remote calls. My project with fully working samples is here.

Tuesday, August 6, 2019

Chicken and egg - resolving Spring properties ahead of a test

Consider a service class responsible for making a remote call and retrieving a detail:


...
public class CitiesService {
    private final WebClient.Builder webClientBuilder;
    private final String baseUrl;

    public CitiesService(
            WebClient.Builder webClientBuilder,
            @Value("${cityservice.url}") String baseUrl) {
        this.webClientBuilder = webClientBuilder;
        this.baseUrl = baseUrl;
    }


    public Flux<City> getCities() {
        return this.webClientBuilder.build()
                .get()
....

This is a Spring Bean and resolves the url to call through a property called "cityservice.url".

If I wanted to test this class, an approach that I have been using when using WebClient is to start a mock server using the excellent Wiremock and using it to test this class. A Wiremock mock looks like this:

    private static final WireMockServer WIREMOCK_SERVER =
            new WireMockServer(wireMockConfig().dynamicPort());


    .....

    WIREMOCK_SERVER.stubFor(get(urlEqualTo("/cities"))
                .withHeader("Accept", equalTo("application/json"))
                .willReturn(aResponse()
                        .withStatus(200)
                        .withHeader("Content-Type", "application/json")
                        .withBody(resultJson)));

The Wiremock server is being started up at a random port and it is set to respond to an endpoint called "/cities". Here is where the chicken and egg problem comes up:

1. The CitiesService class requires a property called "cityservice.url" to be set before starting the test.
2. Wiremock is started at a random port and the url that it is responding to is "http://localhost:randomport" and is available only once the test is kicked off.


There are three potential solutions that I can think of to break this circular dependency:

Approach 1: To use a hardcoded port

This approach depends on starting up Wiremock on a fixed port instead of a dynamic port, this way the property can be set when starting the test up, something like this:

@ExtendWith(SpringExtension.class)
@SpringBootTest(classes = CitiesServiceHardcodedPortTest.SpringConfig.class,
        properties = "cityservice.url=http://localhost:9876")
public class CitiesServiceHardcodedPortTest {
    private static final WireMockServer WIREMOCK_SERVER =
            new WireMockServer(wireMockConfig().port(9876));


Here Wiremock is being started at port 9876 and the property at startup is being set to "http://localhost:9876/".

This solves the problem, however, this is not CI server friendly, it is possible for the ports to collide at runtime and this makes for a flaky test.


Approach 2: Not use Spring for test

A better approach is to not use the property, along these lines:

public class CitiesServiceDirectTest {
    private static final WireMockServer WIREMOCK_SERVER =
            new WireMockServer(wireMockConfig().dynamicPort());

    private CitiesService citiesService;

    @BeforeEach
    public void beforeEachTest() {
        final WebClient.Builder webClientBuilder = WebClient.builder();

        this.citiesService = new CitiesService(webClientBuilder, WIREMOCK_SERVER.baseUrl());
    }


Here the service is being created by explicitly setting the baseUrl in the constructor, thus avoiding the need to set a property ahead of the test.


Approach 3: Application Context Initializer


ApplicationContextInitializer is used for programmatically initializing a Spring Application Context and it can be used with a test to inject in the property before the actual test is executed. Along these lines:

@ExtendWith(SpringExtension.class)
@SpringBootTest(classes = CitiesServiceSpringTest.SpringConfig.class)
@ContextConfiguration(initializers = {CitiesServiceSpringTest.PropertiesInitializer.class})
public class CitiesServiceSpringTest {
    private static final WireMockServer WIREMOCK_SERVER =
            new WireMockServer(wireMockConfig().dynamicPort());

    @Autowired
    private CitiesService citiesService;

    @Test
    public void testGetCitiesCleanFlow() throws Exception {
        ...
    }


    static class PropertiesInitializer implements ApplicationContextInitializer<ConfigurableApplicationContext> {

        @Override
        public void initialize(ConfigurableApplicationContext applicationContext) {
            TestPropertyValues.of(
                    "cityservice.url=" + "http://localhost:" + WIREMOCK_SERVER.port()
            ).applyTo(applicationContext.getEnvironment());
        }
    }

}

Wiremock is started up first, then Spring context is initialized using the initializer which injects in the "cityservice.url" property using the Wiremocks dynamic port, this way the property is available for wiring into CityService.


Conclusion

I personally prefer Approach 2, however it is good to have Spring's wiring and the dependent beans created ahead of the test and if the class utilizes these then I prefer Approach 3. Application Context initializer provides a good way to break the chicken and egg problem with properties like these which need to be available ahead of Spring's context getting engaged.

All the code samples are available here:

Approach 1: https://github.com/bijukunjummen/reactive-cities-demo/blob/master/src/test/java/samples/geo/service/CitiesServiceHardcodedPortTest.java
Approach 2: https://github.com/bijukunjummen/reactive-cities-demo/blob/master/src/test/java/samples/geo/service/CitiesServiceDirectTest.java
Approach 3: https://github.com/bijukunjummen/reactive-cities-demo/blob/master/src/test/java/samples/geo/service/CitiesServiceSpringTest.java

Tuesday, April 30, 2019

Functional Hystrix using Spring Cloud HystrixCommands

Spring's WebClient provides a non-blocking client for making service to service calls. Hystrix, though now in a maintenance mode, has been used for protecting service to service calls by preventing cascading failures, providing circuit breakers for calls to slow or faulty upstream services.

In this post, I will be exploring how Spring Cloud provides a newer functional approach to wrapping a remote call with Hystrix.


Consider a simple service that returns a list of entities, say a list of cities, modeled using the excellent Wiremock tool:

WIREMOCK_SERVER.stubFor(WireMock.get(WireMock.urlMatching("/cities"))
                .withHeader("Accept", WireMock.equalTo("application/json"))
                .willReturn(WireMock.aResponse()
                        .withStatus(HttpStatus.OK.value())
                        .withFixedDelay(5000)
                        .withHeader("Content-Type", "application/json")))

When called with a uri of the type "/cities" this Wiremock endpoint responds with a json of the following type:

[
  {
    "country": "USA",
    "id": 1,
    "name": "Portland",
    "pop": 1600000
  },
  {
    "country": "USA",
    "id": 2,
    "name": "Seattle",
    "pop": 3200000
  },
  {
    "country": "USA",
    "id": 3,
    "name": "SFO",
    "pop": 6400000
  }
]

after a delay of 5 seconds.

Traditional approach


There are many approaches to using Hystrix, I have traditionally preferred an approach where an explicit Hystrix Command protects the remote call, along these lines:

import com.netflix.hystrix.HystrixCommandGroupKey
import com.netflix.hystrix.HystrixCommandKey
import com.netflix.hystrix.HystrixCommandProperties
import com.netflix.hystrix.HystrixObservableCommand
import org.bk.samples.model.City
import org.slf4j.Logger
import org.slf4j.LoggerFactory
import org.springframework.http.MediaType
import org.springframework.web.reactive.function.client.WebClient
import org.springframework.web.reactive.function.client.bodyToFlux
import org.springframework.web.util.UriComponentsBuilder
import reactor.core.publisher.Flux
import rx.Observable
import rx.RxReactiveStreams
import rx.schedulers.Schedulers
import java.net.URI


class CitiesHystrixCommand(
        private val webClientBuilder: WebClient.Builder,
        private val citiesBaseUrl: String
) : HystrixObservableCommand<City>(
        HystrixObservableCommand.Setter
                .withGroupKey(HystrixCommandGroupKey.Factory.asKey("cities-service"))
                .andCommandKey(HystrixCommandKey.Factory.asKey("cities-service"))
                .andCommandPropertiesDefaults(HystrixCommandProperties.Setter()
                        .withExecutionTimeoutInMilliseconds(4000))) {
    override fun construct(): Observable<City> {
        val buildUri: URI = UriComponentsBuilder
                .fromUriString(citiesBaseUrl)
                .path("/cities")
                .build()
                .encode()
                .toUri()

        val webClient: WebClient = this.webClientBuilder.build()

        val result: Flux<City> = webClient.get()
                .uri(buildUri)
                .accept(MediaType.APPLICATION_JSON)
                .exchange()
                .flatMapMany { clientResponse ->
                    clientResponse.bodyToFlux<City>()
                }

        return RxReactiveStreams.toObservable(result)
    }

    override fun resumeWithFallback(): Observable<City> {
        LOGGER.error("Falling back on cities call", executionException)
        return Observable.empty()
    }

    companion object {
        private val LOGGER: Logger = LoggerFactory.getLogger(CitiesHystrixCommand::class.java)
    }
}

This code can now be used to make a remote call the following way:

import org.springframework.http.MediaType
import org.springframework.web.reactive.function.client.WebClient


class CitiesHystrixCommandBasedClient(
        private val webClientBuilder: WebClient.Builder,
        private val citiesBaseUrl: String
) {
    fun getCities(): Flux<City> {
        val citiesObservable: Observable<City> = CitiesHystrixCommand(webClientBuilder, citiesBaseUrl)
                .observe()
                .subscribeOn(Schedulers.io())

        return Flux
                .from(RxReactiveStreams
                        .toPublisher(citiesObservable))
    }
}


Two things to note here,
1. WebClient returns a Project Reactor "Flux" type representing a list of cities, however Hystrix is Rx-Java 1 based, so Flux is being transformed to Rx-Java Observable using "RxReactiveStreams.toObservable()" call, provided by the RxJavaReactiveStreams library here.

2. I still want Project Reactor "Flux" type to be used in the rest of the application, so there is another adapter that converts the Rx-Java Observable back to a Flux - "Flux.from(RxReactiveStreams.toPublisher(citiesObservable))" once the call wrapped in Hystrix returns.


If I were to try this client with the wiremock sample with the 5 second delay, it correctly handles the delay and returns after a second.


Functional approach


There is a lot of boiler-plate with the previous approach which is avoided with the new functional approach of using HystrixCommands, a utility class which comes with Spring Cloud which provides a functional approach to making the remote call wrapped with Hystrix.

The entirety of the call using HystrixCommands looks like this:

import com.netflix.hystrix.HystrixCommandProperties
import org.bk.samples.model.City
import org.slf4j.Logger
import org.slf4j.LoggerFactory
import org.springframework.cloud.netflix.hystrix.HystrixCommands
import org.springframework.http.MediaType
import org.springframework.web.reactive.function.client.WebClient
import org.springframework.web.reactive.function.client.bodyToFlux
import org.springframework.web.util.UriComponentsBuilder
import reactor.core.publisher.Flux
import rx.schedulers.Schedulers
import java.net.URI

class CitiesFunctionalHystrixClient(
        private val webClientBuilder: WebClient.Builder,
        private val citiesBaseUrl: String
) {
    fun getCities(): Flux<City> {
        return HystrixCommands
                .from(callCitiesService())
                .commandName("cities-service")
                .groupName("cities-service")
                .commandProperties(
                        HystrixCommandProperties.Setter()
                                .withExecutionTimeoutInMilliseconds(1000)
                )
                .toObservable { obs ->
                    obs.observe()
                            .subscribeOn(Schedulers.io())
                }
                .fallback { t: Throwable ->
                    LOGGER.error(t.message, t)
                    Flux.empty()
                }
                .toFlux()
    }

    fun callCitiesService(): Flux<City> {
        val buildUri: URI = UriComponentsBuilder
                .fromUriString(citiesBaseUrl)
                .path("/cities")
                .build()
                .encode()
                .toUri()

        val webClient: WebClient = this.webClientBuilder.build()

        return webClient.get()
                .uri(buildUri)
                .accept(MediaType.APPLICATION_JSON)
                .exchange()
                .flatMapMany { clientResponse ->
                    clientResponse.bodyToFlux<City>()
                }
    }

    companion object {
        private val LOGGER: Logger = LoggerFactory.getLogger(CitiesHystrixCommand::class.java)
    }
}


A lot of boiler-plate is avoided with this approach -
1. an explicit command is not required anymore
2. the call and the fallback are coded in a fluent manner
3. Any overrides can be explicitly specified - in this specific instance the timeout of 1 second.

Conclusion

I like the conciseness which HystrixCommands brings to the usage of Hystrix with WebClient. I have the entire sample available in my github repo - https://github.com/bijukunjummen/webclient-hystrix-sample, all the dependencies required to get the samples to work is part of this repo. If you are interested in sticking with Rx-Java 1, then an approach described here may help you avoid boiler-plate with vanilla Hystrix


Friday, January 4, 2019

Unit testing DynamoDB applications using JUnit5

In a previous post I had described the new AWS SDK for Java 2 which provides non-blocking IO support for Java clients calling different AWS services. In this post I will go over an approach that I have followed to unit test the AWS DynamoDB calls.

There are a few ways to spin up a local version of DynamoDB -

1. AWS provides a DynamoDB local
2. Localstack provides a way to spin up a good number of AWS services locally
3. A docker version of DynamoDB Local
4. Dynalite, a node based implementation of DynamoDB


Now to be able to unit test an application, I need to be able to start up an embedded version of DynamoDB using one of these options right before a test runs and then shut it down after a test completes. There are three approaches that I have taken:

1. Using a JUnit 5 extension that internally brings up a AWS DynamoDB Local and spins it down after a test.
2. Using testcontainers to start up a docker version DynamoDB Local
3. Using testcontainers to start up DynaLite

JUnit5 extension

JUnit5 extension provides a convenient hook point to start up an embedded version of DynamoDB for tests. It works by pulling in a version of DynamoDB Local as a maven dependency:

dependencies {
    ...
 testImplementation("com.amazonaws:DynamoDBLocal:1.11.119")
    ...
}

A complication with this dependency is that there are native components (dll, .so etc) that the DynamoDB Local interacts with and to get these in the right place, I depend on a Gradle task:

task copyNativeDeps(type: Copy) {
 mkdir "build/native-libs"
 from(configurations.testCompileClasspath) {
  include '*.dll'
  include '*.dylib'
  include '*.so'
 }
 into 'build/native-libs'
}

test {
 dependsOn copyNativeDeps
}

which puts the native libs in build/native-libs folder, and the extension internally sets this path as a system property:

System.setProperty("sqlite4java.library.path", libPath.toAbsolutePath().toString())

Here is the codebase to the JUnit5 extension with all these already hooked up - https://github.com/bijukunjummen/boot-with-dynamodb/blob/master/src/test/kotlin/sample/dyn/rules/LocalDynamoExtension.kt

A test using this extension looks like this:

class HotelRepoTest {
    companion object {
        @RegisterExtension
        @JvmField
        val localDynamoExtension = LocalDynamoExtension()

        @BeforeAll
        @JvmStatic
        fun beforeAll() {
            val dbMigrator = DbMigrator(localDynamoExtension.syncClient!!)
            dbMigrator.migrate()
        }

    }
    @Test
    fun saveHotel() {
        val hotelRepo = DynamoHotelRepo(localDynamoExtension.asyncClient!!)
        val hotel = Hotel(id = "1", name = "test hotel", address = "test address", state = "OR", zip = "zip")
        val resp = hotelRepo.saveHotel(hotel)

        StepVerifier.create(resp)
                .expectNext(hotel)
                .expectComplete()
                .verify()
    }
}

The code can interact with a fully featured DynamoDB.

TestContainers with DynamoDB Local Docker


The JUnit5 extensions approach works well but it requires an additional dependency with native binaries to be pulled in. A cleaner approach may be to use the excellent Testcontainers to spin up a docker version of DynamoDB Local the following way:

class HotelRepoLocalDynamoTestContainerTest {
    @Test
    fun saveHotel() {
        val hotelRepo = DynamoHotelRepo(getAsyncClient(dynamoDB))
        val hotel = Hotel(id = "1", name = "test hotel", address = "test address", state = "OR", zip = "zip")
        val resp = hotelRepo.saveHotel(hotel)

        StepVerifier.create(resp)
                .expectNext(hotel)
                .expectComplete()
                .verify()
    }


    companion object {
        val dynamoDB: KGenericContainer = KGenericContainer("amazon/dynamodb-local:1.11.119")
                .withExposedPorts(8000)

        @BeforeAll
        @JvmStatic
        fun beforeAll() {
            dynamoDB.start()
        }

        @AfterAll
        @JvmStatic
        fun afterAll() {
            dynamoDB.stop()
        }

        fun getAsyncClient(dynamoDB: KGenericContainer): DynamoDbAsyncClient {
            val endpointUri = "http://" + dynamoDB.getContainerIpAddress() + ":" +
                    dynamoDB.getMappedPort(8000)
            val builder: DynamoDbAsyncClientBuilder = DynamoDbAsyncClient.builder()
                    .endpointOverride(URI.create(endpointUri))
                    .region(Region.US_EAST_1)
                    .credentialsProvider(StaticCredentialsProvider
                            .create(AwsBasicCredentials
                                    .create("acc", "sec")))
            return builder.build()
        }

        ...
    }
}

This code starts up DynamoDB at a random unoccupied port and provides this information so that the client can be created using this information. There is a little Kotlin workaround that I had to do based on an issue reported here - https://github.com/testcontainers/testcontainers-java/issues/318


TestContainers with Dynalite


Dynalite is a javascript based implementation of DynamoDB and can be run for tests again using the TestContainer approach. This time however there is already a TestContainer module for Dynalite. I found that it does not support JUnit5 and sent a Pull request to provide this support, in the iterim the raw docker image can be used and this is how a test looks like:

class HotelRepoDynaliteTestContainerTest {
    @Test
    fun saveHotel() {
        val hotelRepo = DynamoHotelRepo(getAsyncClient(dynamoDB))
        val hotel = Hotel(id = "1", name = "test hotel", address = "test address", state = "OR", zip = "zip")
        val resp = hotelRepo.saveHotel(hotel)

        StepVerifier.create(resp)
                .expectNext(hotel)
                .expectComplete()
                .verify()
    }

    companion object {
        val dynamoDB: KGenericContainer = KGenericContainer("quay.io/testcontainers/dynalite:v1.2.1-1")
                .withExposedPorts(4567)

        @BeforeAll
        @JvmStatic
        fun beforeAll() {
            dynamoDB.start()
            val dbMigrator = DbMigrator(getSyncClient(dynamoDB))
            dbMigrator.migrate()
        }

        @AfterAll
        @JvmStatic
        fun afterAll() {
            dynamoDB.stop()
        }

        fun getAsyncClient(dynamoDB: KGenericContainer): DynamoDbAsyncClient {
            val endpointUri = "http://" + dynamoDB.getContainerIpAddress() + ":" +
                    dynamoDB.getMappedPort(4567)
            val builder: DynamoDbAsyncClientBuilder = DynamoDbAsyncClient.builder()
                    .endpointOverride(URI.create(endpointUri))
                    .region(Region.US_EAST_1)
                    .credentialsProvider(StaticCredentialsProvider
                            .create(AwsBasicCredentials
                                    .create("acc", "sec")))
            return builder.build()
        }
        ...
    }
}

Conclusion

All of the approaches are useful in being able to test integration with DynamoDB. My personal preference is using the TestContainers approach if a docker agent is available else with the JUnit5 extension approach. The samples with fully working tests using all the three approaches are available in my github repo - https://github.com/bijukunjummen/boot-with-dynamodb

Sunday, December 16, 2018

Reactive Spring Webflux with AWS DynamoDB

AWS has released AWS SDK for Java version 2, the SDK now supports non-blocking IO for the API calls of different AWS services. In this post I will be exploring using the DynamoDB API's of the AWS SDK 2.x and using Spring Webflux stack to expose a reactive endpoint - this way the application is reactive end to end and presumably should use resources very efficiently (I have plans to do some tests on this set-up as a follow up).


Details of the Application


It may be easier to simply look at the code and follow it there - it is available in my GitHub repo.

The application is a simple one - to perform CRUD operation on a Hotel entity represented using the following Kotlin code:

data class Hotel(
        val id: String = UUID.randomUUID().toString(),
        val name: String? = null,
        val address: String? = null,
        val state: String? = null,
        val zip: String? = null
)

I want to expose endpoints to save and retrieve a hotel entity and to get the list of hotels by state.


Details of the AWS SDK 2


The package names of the AWS SDK 2 api's all start with "software.amazon.awssdk" prefix now, the client to interact with DynamoDB is created using code along these lines:

import software.amazon.awssdk.auth.credentials.DefaultCredentialsProvider
import software.amazon.awssdk.regions.Region
import software.amazon.awssdk.services.dynamodb.DynamoDbAsyncClient

val client: DynamoDbAsyncClient = DynamoDbAsyncClient.builder()
        .region(Region.of(dynamoProperties.region))
        .credentialsProvider(DefaultCredentialsProvider.builder().build())
        .build()


Once the DynamoDbAsyncClient instance is created, any operation using this client returns a Java 8 CompletableFuture type. For eg. in saving a Hotel entity:

val putItemRequest = PutItemRequest.builder()
        .tableName("hotels")
        .item(HotelMapper.toMap(hotel))
        .build()
        
val result: CompletableFuture<PutItemResponse> =
        dynamoClient.putItem(putItemRequest)

and in retrieving a record by id:

val getItemRequest: GetItemRequest = GetItemRequest.builder()
        .key(mapOf(Constants.ID to AttributeValue.builder().s(id).build()))
        .tableName(Constants.TABLE_NAME)
        .build()

val response: CompletableFuture<GetItemResponse> = dynamoClient.getItem(getItemRequest)

CompletableFuture provides a comprehensive set of functions to transform the results when available.

Integrating with Spring Webflux

Spring Webflux is a reactive web framework. The non-blocking IO support in AWS SDK 2 now makes it possible to write an end to end reactive and non-blocking applications with DynamoDB. Spring Webflux uses reactor-core to provide reactive streams support and the trick to integrating with AWS SDK 2 is to transform the Java 8 CompletableFuture to a reactor-core type, the following way when retrieving an item from DynamoDB by id:

val getItemRequest: GetItemRequest = GetItemRequest.builder()
        .key(mapOf(Constants.ID to AttributeValue.builder().s(id).build()))
        .tableName(Constants.TABLE_NAME)
        .build()

return Mono.fromCompletionStage(dynamoClient.getItem(getItemRequest))
        .map { resp ->
            HotelMapper.fromMap(id, resp.item())
        }

Spring Webflux expects the return types of the different web endpoint method signatures to be of reactive types, so a typical endpoint for getting say a list of hotels is the following:

@RequestMapping(value = ["/hotels"], method = [RequestMethod.GET])
fun getHotelsByState(@RequestParam("state") state: String): Flux<Hotel> {
    return hotelRepo.findHotelsByState(state)
}

Spring Webflux also supports a functional way to describe the API of the application, so an equivalent API to retrieve a hotel by its id, but expressed as a functional DSL is the following:

@Configuration
class HotelAdditionalRoutes {

    @Bean
    fun routes(hotelRepo: HotelRepo) = router {
        GET("/hotels/{id}") { req ->
            val id = req.pathVariable("id")
            val response: Mono<ServerResponse> = hotelRepo.getHotel(id)
                    .flatMap { hotel ->
                        ServerResponse.ok().body(BodyInserters.fromObject(hotel))
                    }
            response.switchIfEmpty(ServerResponse.notFound().build())
        }
    }
}


Conclusion

AWS SDK 2 makes it simple to write an end to end reactive and non-blocking applications. I have used Spring Webflux and AWS SDK 2 dynamo client to write such an application here. The entire working sample is available in my GitHub repo - https://github.com/bijukunjummen/boot-with-dynamodb, and has instructions on how to start up a local version of DynamoDB and use it for testing the application.


Tuesday, September 4, 2018

Knative Serving - Service to Service call

In a previous post I had covered using Knative's Serving feature to run a sample Java Application. This post will be go into the steps to deploy two applications, with one application calling the other.


Details of the Sample

The entire sample is available at my github repository - https://github.com/bijukunjummen/sleuth-webflux-sample.

The applications are Spring Boot based. The backend application exposes an endpoint "/messages" when invoked with a payload which looks like this:

{
    "delay": "0",
    "id": "123",
    "payload": "test",
    "throw_exception": "true"
}

would respond after the specified delay. If the payload has the "throw_exception" flag set to true, then it would return a 5XX after the specified delay.

The client application exposes a "/passthrough/messages" endpoint, which takes in the exact same payload and simply forwards it to the backend application. The url to the backend app is passed to the client app as a "LOAD_TARGET_URL" environment property.


Deploying as a Knative Serving service

The subfolder to this project - knative, holds the manifest for deploying the Knative serving Service for the 2 applications. The backend application's knative service manifest looks like this:

apiVersion: serving.knative.dev/v1alpha1
kind: Service
metadata:
  name: sample-backend-app
  namespace: default
spec:
  runLatest:
    configuration:
      revisionTemplate:
        spec:
          container:
            image: bijukunjummen/sample-backend-app:0.0.1-SNAPSHOT
            env:
            - name: VERSION
              value: "0.0.2-SNAPSHOT"
            - name: SERVER_PORT
              value: "8080"

The client app has to point to the backend service and is specified in the specs:

apiVersion: serving.knative.dev/v1alpha1
kind: Service
metadata:
  name: sample-client-app
  namespace: default
spec:
  runLatest:
    configuration:
      revisionTemplate:
        spec:
          container:
            image: bijukunjummen/sample-client-app:0.0.2-SNAPSHOT
            env:
            - name: VERSION
              value: "0.0.1-SNAPSHOT"
            - name: LOAD_TARGET_URL
              value: http://sample-backend-app.default.svc.cluster.local
            - name: SERVER_PORT
              value: "8080"


The domain "sample-backend-app.default.svc.cluster.local", points to the dns name of the backend service created by the Knative serving service resource


Testing

It was easier for me to simply create a small video with how I tested this:


As in my previous post, the request to the application is via the knative ingress gateway, the url to which can be obtained the following way(for a minikube environment):

export GATEWAY_URL=$(echo $(minikube ip):$(kubectl get svc knative-ingressgateway -n istio-system -o 'jsonpath={.spec.ports[?(@.port==80)].nodePort}'))

And a sample request made the following way, note that the routing in the Gateway is via the host header, in this instance "sample-client-app.default.example.com":

export CLIENT_DOMAIN=$(kubectl get services.serving.knative.dev sample-client-app  -o="jsonpath={.status.domain}")

http http://${GATEWAY_URL}/passthrough/messages Host:"${CLIENT_DOMAIN}" id=1 payload=test delay=100 throw_exception=false


Sunday, July 29, 2018

"Knative Serving" for Spring Boot Applications

I got a chance to try Knative's Serving feature to deploy a Spring Boot application and this post is simply documenting a sample and the approach I took.

I don't understand the internals of Knative enough yet to have an opinion on whether this approach is better than the deployment + services + ingress based approach.

One feature that is awesome is the auto-scaling feature in Knative Serving, which based on the load, increases/decreases the number of pods as part of a "Deployment" handling the request.

Details of the Sample


My entire sample is available here and it is mostly developed based on the java sample available with Knative Serving documentation. I used Knative with a minikube environment to try the sample.


Deploying to Kubernetes/Knative

Assuming that a Kubernetes environment with Istio and Knative has been set-up, the way to run the application is to deploy a Kubernetes manifest this way:

apiVersion: serving.knative.dev/v1alpha1
kind: Service
metadata:
  name: sample-boot-knative-service
  namespace: default
spec:
  runLatest:
    configuration:
      revisionTemplate:
        spec:
          container:
            image: bijukunjummen/sample-boot-knative-app:0.0.1-SNAPSHOT

The image "bijukunjummen/sample-boot-knative-app:0.0.1-SNAPSHOT" is publicly available via Dockerhub, so this sample should work out of the box.

Applying this manifest:

kubectl apply -f service.yml

should register a Knative Serving Service resource with Kubernetes, the Knative serving services resource manages the lifecycle of other Knative resources (configuration, revision, route) the details of which can be viewed using the following commands, if anything goes wrong, the details should show up in the output:

kubectl get services.serving.knative.dev sample-boot-knative-service -o yaml

Testing

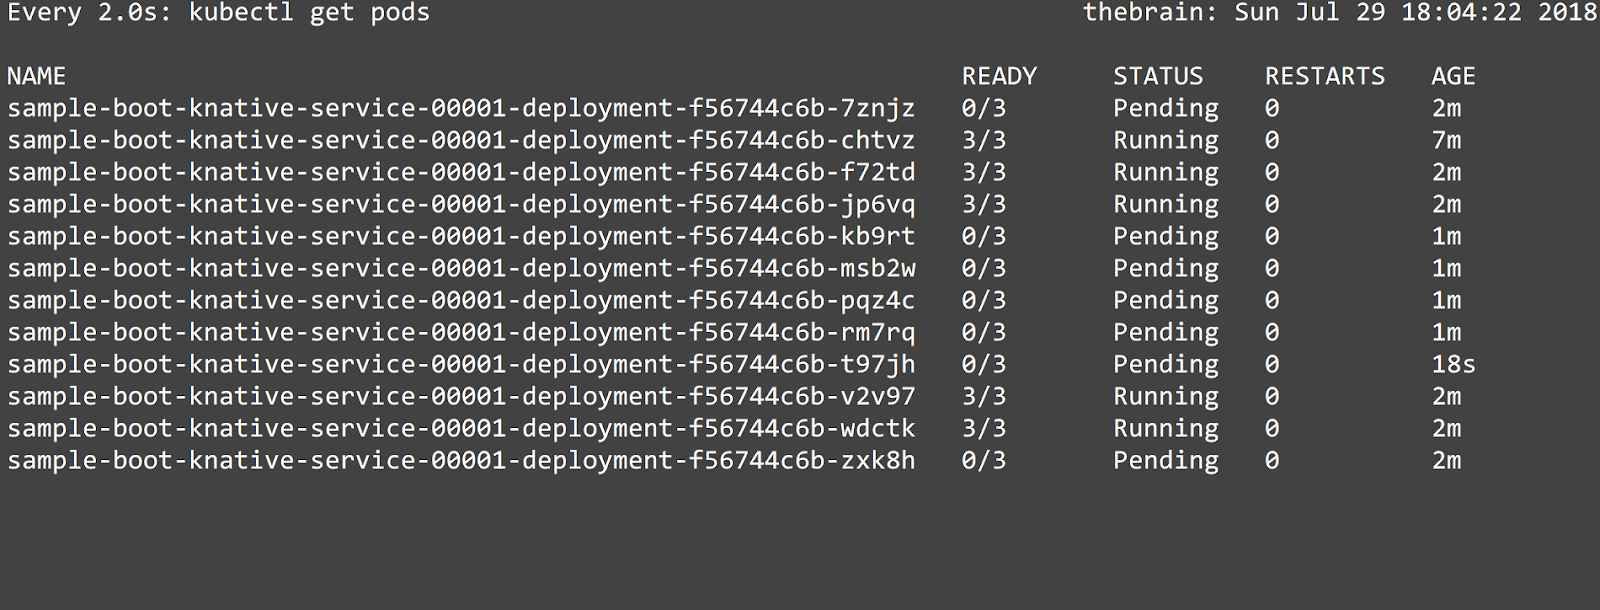
Assuming that the Knative serving service is deployed cleanly, the first oddity to see is that no pods show up for the application!


If I were to make a request to the app now, which is done via a routing layer managed by Knative - this can be retrieved for a minikube environment using the following bash script:

export GATEWAY_URL=$(echo $(minikube ip):$(kubectl get svc knative-ingressgateway -n istio-system -o 'jsonpath={.spec.ports[?(@.port==80)].nodePort}'))
export APP_DOMAIN=$(kubectl get services.serving.knative.dev sample-boot-knative-service  -o="jsonpath={.status.domain}")

and making a call to an endpoint of the app using CUrl:

curl -X "POST" "http://${GATEWAY_URL}/messages" \
     -H "Accept: application/json" \
     -H "Content-Type: application/json" \
     -H "Host: ${APP_DOMAIN}" \
     -d $'{
  "id": "1",
  "payload": "one",
  "delay": "300"
}'
OR httpie

http http://${GATEWAY_URL}/messages Host:"${APP_DOMAIN}" id=1 payload=test delay=100

should magically, using the auto-scaler component start spinning up the pods to handle the request:


The first request took almost 17 seconds to complete, the time it takes to spin up a pod, but subsequent requests are quick.

Now, to show the real power of auto-scaler I ran a small load test with a 50 user load and pods are scaled up and down as required.


Conclusion

I can see the promise of Knative in automatically managing the resources, once defined using a fairly simple manifest, in a Kubernetes environment and letting a developer focus on the code and logic.

Thursday, July 19, 2018

Jib - Building docker image for a Spring Boot App

I was pleasantly surprised by how easy it was to create a docker image for a sample Spring Boot application using Jib.

Let me first contrast Jib with an approach that I was using before.

I was creating docker images using bmuschko's excellent gradle-docker plugin. Given access to a docker daemon and a gradle dsl based description of the Dockerfile or a straight Dockerfile, it would create the docker image using a gradle task. In my case, the task to create the docker image looks something like this:

task createDockerImage(type: DockerBuildImage) {
    inputDir = file('.')
    dockerFile = project.file('docker/Dockerfile')
    tags = ['sample-micrometer-app:' + project.version]
}

createDockerImage.dependsOn build

and my Dockerfile itself derived off "java:8" base image:

FROM java:8
...

gradle-docker-plugin made it simple to create a docker image right from gradle with the catch that the plugin needs access to a docker daemon to create the image. Also since the base "java:8" image is large the final docker image turns out to be around 705MB on my machine. Again no fault of the gradle-docker plugin but based on my choice of base image.


Now with Jib, all I have to do is to add the plugin:

plugins {
    id 'com.google.cloud.tools.jib' version '0.9.6'
}

Configure it to give the image a name:

jib {
    to {
        image = "sample-micrometer-app:0.0.1-SNAPSHOT"
    }
}

And that is it. With a local docker daemon available, I can create my docker image using the following task:


./gradlew jibDockerBuild

Jib automatically selects a very lightweight base image - my new image is just about 150 MB in size.

If I had access to a docker registry available then the local docker daemon is not required, it can directly create and publish the image to a docker registry!

Jib gradle plugin provides an interesting task - "jibExportDockerContext" to export out the docker file, this way if needed a docker build can be run using this Dockerfile, for my purposes I wanted to see the contents of this file and it looks something like this:

FROM gcr.io/distroless/java

COPY libs /app/libs/
COPY resources /app/resources/
COPY classes /app/classes/

ENTRYPOINT ["java","-cp","/app/libs/*:/app/resources/:/app/classes/","sample.meter.SampleServiceAppKt"]


All in all, a very smooth experience and Jib does live up to its goals. My sample project with jib integrated with a gradle build is available here.


Friday, June 22, 2018

Tracing a reactive flow - Using Spring Cloud Sleuth with Boot 2

Spring Cloud Sleuth which adds Spring instrumentation support on top of OpenZipkin Brave makes distributed tracing trivially simple for Spring Boot applications. This is a quick write up on what it takes to add support for distributed tracing using this excellent library.

Consider two applications - a client application which uses an upstream service application, both using Spring WebFlux, the reactive web stack for Spring:


My objective is to ensure that flows from user to the client application to the service application can be traced and latencies cleanly recorded for requests.


The final topology that Spring Cloud Sleuth enables is the following:


The sampled trace information from the client and the service app is exported to Zipkin via a queuing mechanism like RabbitMQ.


So what are the changes required to the client and the service app - like I said it is trivially simple! The following libraries need to be pulled in - in my case via gradle:

compile("org.springframework.cloud:spring-cloud-starter-sleuth")
 compile("org.springframework.cloud:spring-cloud-starter-zipkin")
 compile("org.springframework.amqp:spring-rabbit")

The versions are not specified as they are expected to be pulled in via Spring Cloud BOM and thanks to Spring Gradle Dependency Management plugin:


ext {
    springCloudVersion = 'Finchley.RELEASE'
}

apply plugin: 'io.spring.dependency-management'

dependencyManagement {
    imports {
        mavenBom "org.springframework.cloud:spring-cloud-dependencies:${springCloudVersion}"
    }
}

And that is actually it, any logs from the application should now start recording the trace and the spans, see how he traceid carried forward in the following logs spanning two different services:

2018-06-22 04:06:28.579  INFO [sample-client-app,c3d507df405b8aaf,c3d507df405b8aaf,true] 9 --- [server-epoll-13] sample.load.PassThroughHandler           : handling message: Message(id=null, payload=Test, delay=1000)
2018-06-22 04:06:28.586  INFO [sample-service-app,c3d507df405b8aaf,829fde759da15e63,true] 8 --- [server-epoll-11] sample.load.MessageHandler               : Handling message: Message(id=5e7ba240-f97d-405a-9633-5540bbfe0df1, payload=Test, delay=1000)

Further the Zipkin UI records the exported information and can visually show a sample trace the following way:


This sample is available in my github repository here - https://github.com/bijukunjummen/sleuth-webflux-sample and can be started up easily using docker-compose with all the dependencies wired in.